The Packet Parser Crate
By Cyprien Avico
www.linkedin.com/in/cyprien-avico
The repo of the crate: GitHub - Packet Parser
The crate link: crates.io - packet_parser
The API reference: docs.rs - packet_parser
This is not a Rust doc. This is a documentation on how I personally parse packets.
Feel free to criticize, do a PR, or send me a message on LinkedIn.
Introduction
Packet Parser is a Rust library designed for parsing network frames.
This book explains how I developed it and its internal architecture, so you can contribute.
Key Features
- Multi-layer support: parses the data link, internet, transport and application layers.
- Zero-copy: the result,
PacketFlow, borrows the input buffer. No payload is copied. - Fail-closed on the link layer: the LINKTYPE is given by the caller, never guessed from the bytes. An unsupported LINKTYPE is an error.
- Fail-soft above it: an unknown or malformed upper layer does not fail the whole parse. The layer stays
None, and a recognized-but-invalid layer is reported incorrupted. - Data validation: every protocol struct is built through
TryFrom, with its checks in a dedicated module. - Precise error management: each layer and each protocol has its own error type, built with
thiserror. - Designed not to panic on hostile bytes: every index follows an explicit length check,
unwrap/expect/panic!are flagged by clippy lints that the CI turns into errors, and the parsers are fuzzed continuously. This is a discipline backed by tooling, not a proof: see the validation chapter for what is and is not guaranteed. - Tunnels: CAPWAP, GRE, IP-in-IP, VXLAN, Geneve and GTP-U are peeled, and the inner packet is parsed recursively.
- Extensibility: a modular architecture that makes adding a protocol a mechanical job.
Reference version
This book describes packet_parser 11.2.0 (crates.io, tag v11.2.0 in the repository). Code excerpts of the crate's internals are quoted from that revision; the user-facing snippets marked tested are compiled and run against it by the book's examples/ crate. When the crate moves, the book is updated with it and this line changes.
Purpose of this crate
The goal of this crate is to provide a function that transforms a packet, or a list of bytes to be more precise, into a typed structure, or into an error if you are getting fooled and receive incoherent bytes.
- You can provide a full network packet with its LINKTYPE, and
parsereturns aPacketFlow: a structured representation containing the data link, internet, transport and application layers. - It is not restricted to a specific layer: every protocol struct implements
TryFrom<&[u8]>. You can pass a TCP payload toTlsPacket::try_from,DnsPacket::try_from,NtpPacket::try_from... and get the detailed structure of that protocol.
To explain how I made this crate, let's dive into packet parsing, my passion.
- First we get started with the public API.
- Then we have to know what I call a packet, because that is what we are starting from, and what the
PacketFlowstruct looks like once the packet is parsed. - Then we'll see the data validation procedure I use for every struct in this crate:
TryFrom. - Then we go down layer by layer: data link, internet, transport, application and tunnels.
- And finally, how to add a new protocol.
Getting started
This chapter is the "how do I use it" part. The rest of the book is the "how is it built" part.
Reference version:
packet_parser11.2.0. Every code snippet marked tested below is included verbatim from the book'sexamples/crate, which compiles and runs against that exact version (cd examples && cargo test). Older versions differ: seeMIGRATION-11.mdin the crate repository.
Installation
[dependencies]
packet_parser = "11.2.0"
hex = "0.4" # only for the examples below, to decode hex dumps
Parse one packet
parse is the entry point. It takes two things:
- the LINKTYPE of the capture: the value stored in the PCAP/PCAPNG file (
LinkType::ETHERNET,LinkType::LINUX_SLL, ...); - exactly one packet, without any PCAP record header.
use packet_parser::{LinkType, parse};

fn main() -> Result<(), Box<dyn std::error::Error>> {
    let raw = hex::decode(
        "feaa81e86d1efeaa818ec864080045500034000000003d06206b36e6700d\
         ac140a0201bbc1087d7f02aa4e2b998e80100081748300000101080a9373\
         c9c207ef14e3",
    )?;

    // Always pass the LINKTYPE the capture declares.
    let flow = parse(LinkType::ETHERNET, &raw)?;

    println!("L2: {}", flow.data_link);

    if let Some(internet) = &flow.internet {
        println!("L3: {} {:?} -> {:?}",
            internet.protocol_name, internet.source, internet.destination);
    }
    if let Some(transport) = &flow.transport {
        println!("L4: {:?} {:?} -> {:?}",
            transport.protocol, transport.source_port, transport.destination_port);
    }
    if let Some(application) = &flow.application {
        println!("L7: {}", application.application_protocol);
    }
    Ok(())
}
Output:
L2:
    Destination MAC: fe:aa:81:e8:6d:1e,
    Source MAC: fe:aa:81:8e:c8:64,
    Ethertype: IPv4,
    VLAN: None,
    Payload Length: 52

L3: IPv4 Some(54.230.112.13) -> Some(172.20.10.2)
L4: Tcp Some(443) -> Some(49416)
No L7 line: this segment is a pure ACK with an empty payload, so there is nothing to classify and application stays None.
The same frame, as the book's example crate checks it (tested):
#![allow(unused)]
fn main() {
    #[test]
    fn parse_a_valid_ethernet_frame() -> Result<(), Box<dyn std::error::Error>> {
        let raw = hex::decode(ETHERNET_IPV4_TCP_ACK_HEX)?;

        // Always pass the LINKTYPE the capture declares.
        let flow = parse(LinkType::ETHERNET, &raw)?;

        let internet = flow.internet.as_ref().expect("IPv4 announced by the EtherType");
        assert_eq!(internet.protocol_name, "IPv4");
        assert_eq!(internet.source.unwrap().to_string(), "54.230.112.13");
        assert_eq!(internet.destination.unwrap().to_string(), "172.20.10.2");

        let transport = flow.transport.as_ref().expect("TCP announced by the IP header");
        assert_eq!(transport.source_port, Some(443));
        assert_eq!(transport.destination_port, Some(49416));

        // A pure ACK: the payload is empty, so there is nothing to classify.
        assert!(flow.application.is_none());
        assert!(flow.corrupted.is_none());
        Ok(())
    }
}
Never guess the LINKTYPE
parse is fail-closed on the link layer: the LINKTYPE comes from the caller and is never guessed from the bytes. Check it up front to reject a whole capture before reading a single packet:
#![allow(unused)]
fn main() {
use packet_parser::{LinkType, is_supported, parse};

let link_type = LinkType::ETHERNET;
if !is_supported(link_type) {
    return Err(format!("unsupported LINKTYPE {}", link_type).into());
}
let flow = parse(link_type, packet_bytes)?;
}
| LINKTYPE | Value | Decoder status |
|---|---|---|
| BSD loopback (NULL) | 0 | Supported: four address-family bytes, then the IP packet (11.2.0) |
| Ethernet | 1 | Supported (802.1Q and 802.1ad/QinQ tags included) |
| RAW IP | 101 | Supported for IPv4 and IPv6 |
| Native IEEE 802.11 | 105 | Modelled for CAPWAP inner flows; top-level decoder not yet supported |
| Linux SLL v1 | 113 | Supported |
| Bluetooth H4 with pseudo-header | 201 | Identified, explicitly unsupported |
| IPv4 raw | 228 | Supported |
| IPv6 raw | 229 | Supported |
| IEEE 802.3br mPacket | 274 | Supported for express mPackets (SMD-E); preemptible fragments are refused |
| Linux SLL v2 | 276 | Supported |
| Any other value | Preserved as-is | ParseError::UnsupportedLinkType |
PacketFlow::try_from(&[u8]) and DataLink::try_from(&[u8]) still exist. They take a bare byte slice and assume Ethernet. Feeding them a Linux any capture (LINKTYPE_LINUX_SLL) does not fail: the 16 cooked-header bytes are read as MAC addresses and an EtherType, and you get Ok with fabricated addresses. Use them only when the capture is known to be Ethernet.
Reading the outcome
Only the link layer can fail the parse. Above it, three outcomes are distinct and must not be confused:
flow.internet / transport | flow.corrupted | Meaning |
|---|---|---|
Some(..) | None | The layer was recognized and decoded. |
None | None | The protocol is not supported (e.g. LLDP EtherType), nothing above it can be reached. |
None | Some(..) | The layer was recognized (by its EtherType or IP protocol number) but its bytes are invalid. CorruptedLayer::layer says which one, error says why. |
Some(..) | Some(..) | Semantic anomaly: the header is readable but no conforming stack emits it (TCP SYN+FIN, reserved bits set). The layer is kept so its ports remain available for flow correlation; nothing is parsed above it. |
A recognized layer with invalid bytes (tested):
#![allow(unused)]
fn main() {
    #[test]
    fn a_recognized_but_invalid_upper_layer_is_reported_not_fatal() {
        let raw = hex::decode(ETHERNET_IPV4_TCP_ACK_HEX).unwrap();

        // Cut 6 bytes into the IPv4 header: the EtherType still says IPv4,
        // so the layer is recognized, but its bytes are invalid.
        let flow = parse(LinkType::ETHERNET, &raw[..20]).unwrap();

        assert!(flow.data_link.as_ethernet().is_some()); // kept
        assert!(flow.internet.is_none());
        let corrupted = flow.corrupted.expect("recognized layer with invalid bytes");
        assert_eq!(corrupted.layer, CorruptedLayerKind::Internet);
        assert_eq!(
            corrupted.error,
            "IPv4 error: Invalid IPv4 packet length: expected at least 20 bytes, got 6 bytes"
        );
    }
}
An unsupported protocol above the link layer, which is not corruption (tested):
#![allow(unused)]
fn main() {
    #[test]
    fn an_unsupported_upper_layer_leaves_the_layer_none_without_corruption() {
        // Synthetic frame: two MAC addresses, EtherType 0x88CC (LLDP, not
        // decoded by the crate) and a few payload bytes.
        let mut raw = hex::decode("0180c200000e001122334455").unwrap();
        raw.extend_from_slice(&[0x88, 0xcc, 0x02, 0x07, 0x04, 0x00, 0x11, 0x22, 0x33, 0x44, 0x55]);

        let flow = parse(LinkType::ETHERNET, &raw).unwrap();

        // Not supported is not the same as corrupt: nothing above the link
        // layer could be reached, and nothing is reported as invalid.
        assert!(flow.internet.is_none());
        assert!(flow.transport.is_none());
        assert!(flow.application.is_none());
        assert!(flow.corrupted.is_none());
    }
}
And the two link-layer failures, the only ones that return Err (tested):
#![allow(unused)]
fn main() {
    #[test]
    fn an_unsupported_linktype_is_refused_before_reading_bytes() {
        let raw = hex::decode(ETHERNET_IPV4_TCP_ACK_HEX).unwrap();
        let bluetooth = LinkType::BLUETOOTH_HCI_H4_WITH_PHDR;

        assert!(!is_supported(bluetooth));
        assert!(matches!(
            parse(bluetooth, &raw),
            Err(ParseError::UnsupportedLinkType(LinkType(201)))
        ));
    }
}
#![allow(unused)]
fn main() {
    #[test]
    fn a_truncated_link_header_fails_the_parse() {
        let raw = hex::decode(ETHERNET_IPV4_TCP_ACK_HEX).unwrap();

        // Only the link layer can fail the parse: 10 bytes cannot hold the
        // 14-byte Ethernet header.
        let error = parse(LinkType::ETHERNET, &raw[..10]).unwrap_err();
        assert_eq!(
            error.to_string(),
            "Invalid link layer: LINKTYPE 1 packet is truncated: required bytes 14, actual bytes 10"
        );
    }
}
Main API
| Need | API |
|---|---|
| Check whether a link decoder exists | is_supported(LinkType) |
| Parse a packet (canonical) | parse(LinkType, &[u8]) |
| Parse with caller-declared ports ("Decode As") | parse_with(LinkType, &[u8], &ParseConfig) |
| Parse Ethernet, compat shortcut (assumes Ethernet) | PacketFlow::try_from(&[u8]) |
| Parse only Ethernet/VLAN (assumes Ethernet) | DataLink::try_from(&[u8]) |
| Parse only L3 | Internet::try_from_network_parts(NetworkProtocol, &[u8]) |
| Parse only L4 | Transport::try_from_parts(Option<TransportProtocol>, &[u8]) |
| Parse one application protocol in detail | packet_parser::parse::application::protocols::<proto>::XxxPacket::try_from(&[u8]) |
| Detach the result from the original buffer | flow.to_owned_flow() |
| Iterate over encapsulated flows | flow.flatten() |
| Verify a checksum (opt-in) | packet_parser::checksum::verify_{ipv4_header,tcp,udp}_checksum |
| Measure the time spent per layer | parse_timed(...) with the parse_timing feature |
"Decode As": my FTP runs on port 2121
Some protocols are only detected when the port and the content agree (see the application chapter). ParseConfig lets the caller declare extra ports. The port never replaces the content check: it only gives the probe its chance before the rest of the table.
#![allow(unused)]
fn main() {
use packet_parser::{DecodeAsProtocol, LinkType, ParseConfig, parse_with};

let config = ParseConfig::new().decode_as(2121, DecodeAsProtocol::Ftp);
let flow = parse_with(LinkType::ETHERNET, &raw, &config)?;
}
Owned flows and serialization
PacketFlow<'a> borrows the input buffer: it cannot outlive it. To store a flow, send it across threads or keep it after the capture buffer is reused, convert it with to_owned_flow(). The conversion is lossy on purpose: the owned form drops the payloads and the per-layer details, and keeps the flow identity (addresses, protocols, ports).
PacketFlow and PacketFlowOwned both implement serde::Serialize and produce the same JSON: the link layer is nested and tagged, the upper layers are flattened, payloads and details are not serialized.
{
  "data_link": {
    "link_type": 1,
    "network_protocol": { "kind": "ipv4" },
    "link_kind": "ethernet",
    "link_details": {
      "destination_mac": "fe:aa:81:e8:6d:1e",
      "source_mac": "fe:aa:81:8e:c8:64",
      "ethertype": "IPv4"
    }
  },
  "source_ip": "54.230.112.13",
  "ip_source_type": "Public",
  "destination_ip": "172.20.10.2",
  "ip_destination_type": "Private",
  "protocol_internet": "IPv4",
  "protocol_transport": "TCP",
  "source_port": 443,
  "destination_port": 49416
}
The owned form is what you keep once the capture buffer is gone (tested):
#![allow(unused)]
fn main() {
    #[test]
    fn owned_flows_serialize_like_borrowed_ones() -> Result<(), Box<dyn std::error::Error>> {
        let raw = hex::decode(ETHERNET_IPV4_TCP_ACK_HEX)?;
        let flow = parse(LinkType::ETHERNET, &raw)?;

        // The owned form outlives the buffer; it drops payloads and details.
        let owned = flow.to_owned_flow();
        drop(raw);

        let json: serde_json::Value = serde_json::from_str(&serde_json::to_string(&owned)?)?;
        assert_eq!(json["data_link"]["link_type"], 1);
        assert_eq!(json["data_link"]["link_kind"], "ethernet");
        assert_eq!(json["source_ip"], "54.230.112.13");
        assert_eq!(json["protocol_transport"], "TCP");
        assert_eq!(json["destination_port"], 49416);
        Ok(())
    }
}
Timing (benchmarks)
parse_timed runs the exact same pipeline as parse and reports the nanoseconds spent in each layer. The API is always there; without the parse_timing feature nothing is measured and ParseTiming stays zeroed, so enabling the feature anywhere in a dependency graph never changes a signature.
#![allow(unused)]
fn main() {
use packet_parser::{LinkType, parse_timed, timing::ParseTiming};

let mut timing = ParseTiming::default();
let flow = parse_timed(LinkType::ETHERNET, &raw, &mut timing)?;
println!("L2={}ns L3={}ns L4={}ns L7={}ns total={}ns",
    timing.l2_ns, timing.l3_ns, timing.l4_ns, timing.l7_ns, timing.total_ns);
}
cargo test --features parse_timing
Known limitations
- No TCP reassembly, no IP reassembly: the parser is stateless and sees one packet at a time.
- The application layer is a classification, not a decode (see the application chapter and the GIOP focus for the tested example).
- Checksums are never validated during parsing (hardware offloading leaves them uncomputed on sender-side captures). Use the
checksummodule when your context allows it.
Packet Structure and Parsing Approach
What is a Packet?
A network packet is a sequence of bytes transmitted over a network. Here's an example of a raw packet in hexadecimal format:
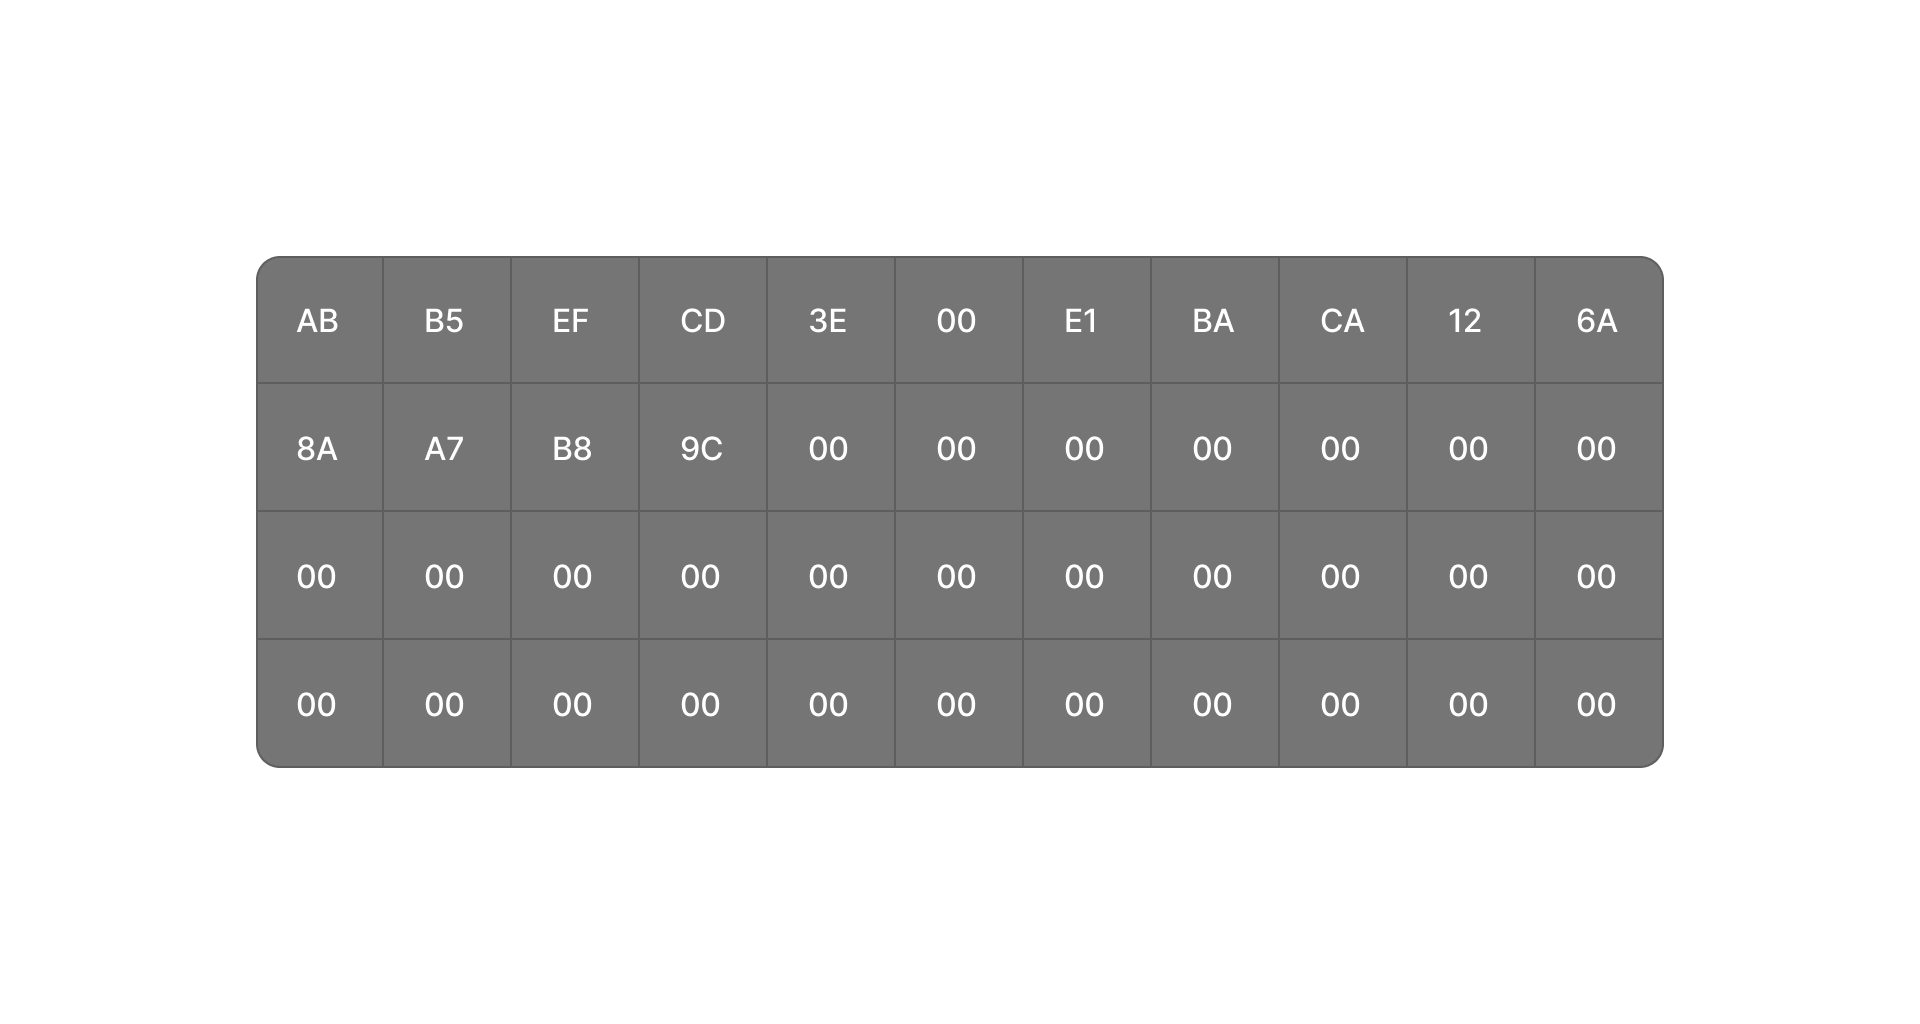
A packet is essentially a list of bytes representing network data.
For example:
#![allow(unused)]
fn main() {
let packet: &[u8] = &[0x00, 0x11, 0x22, 0x33, 0x44, 0x55, /* other bytes */];
}
It is preferable to reference the packet (&[u8]) rather than copying it to avoid unnecessary memory usage and improve performance. This is the founding rule of the crate: the parsed structures borrow the packet, they never copy it. Every parsed struct carries a lifetime 'a tied to the input buffer.
🎨 Identifying Protocols in the Packet
Each protocol occupies a specific part of the packet. By analyzing the bytes, we can identify different layers.
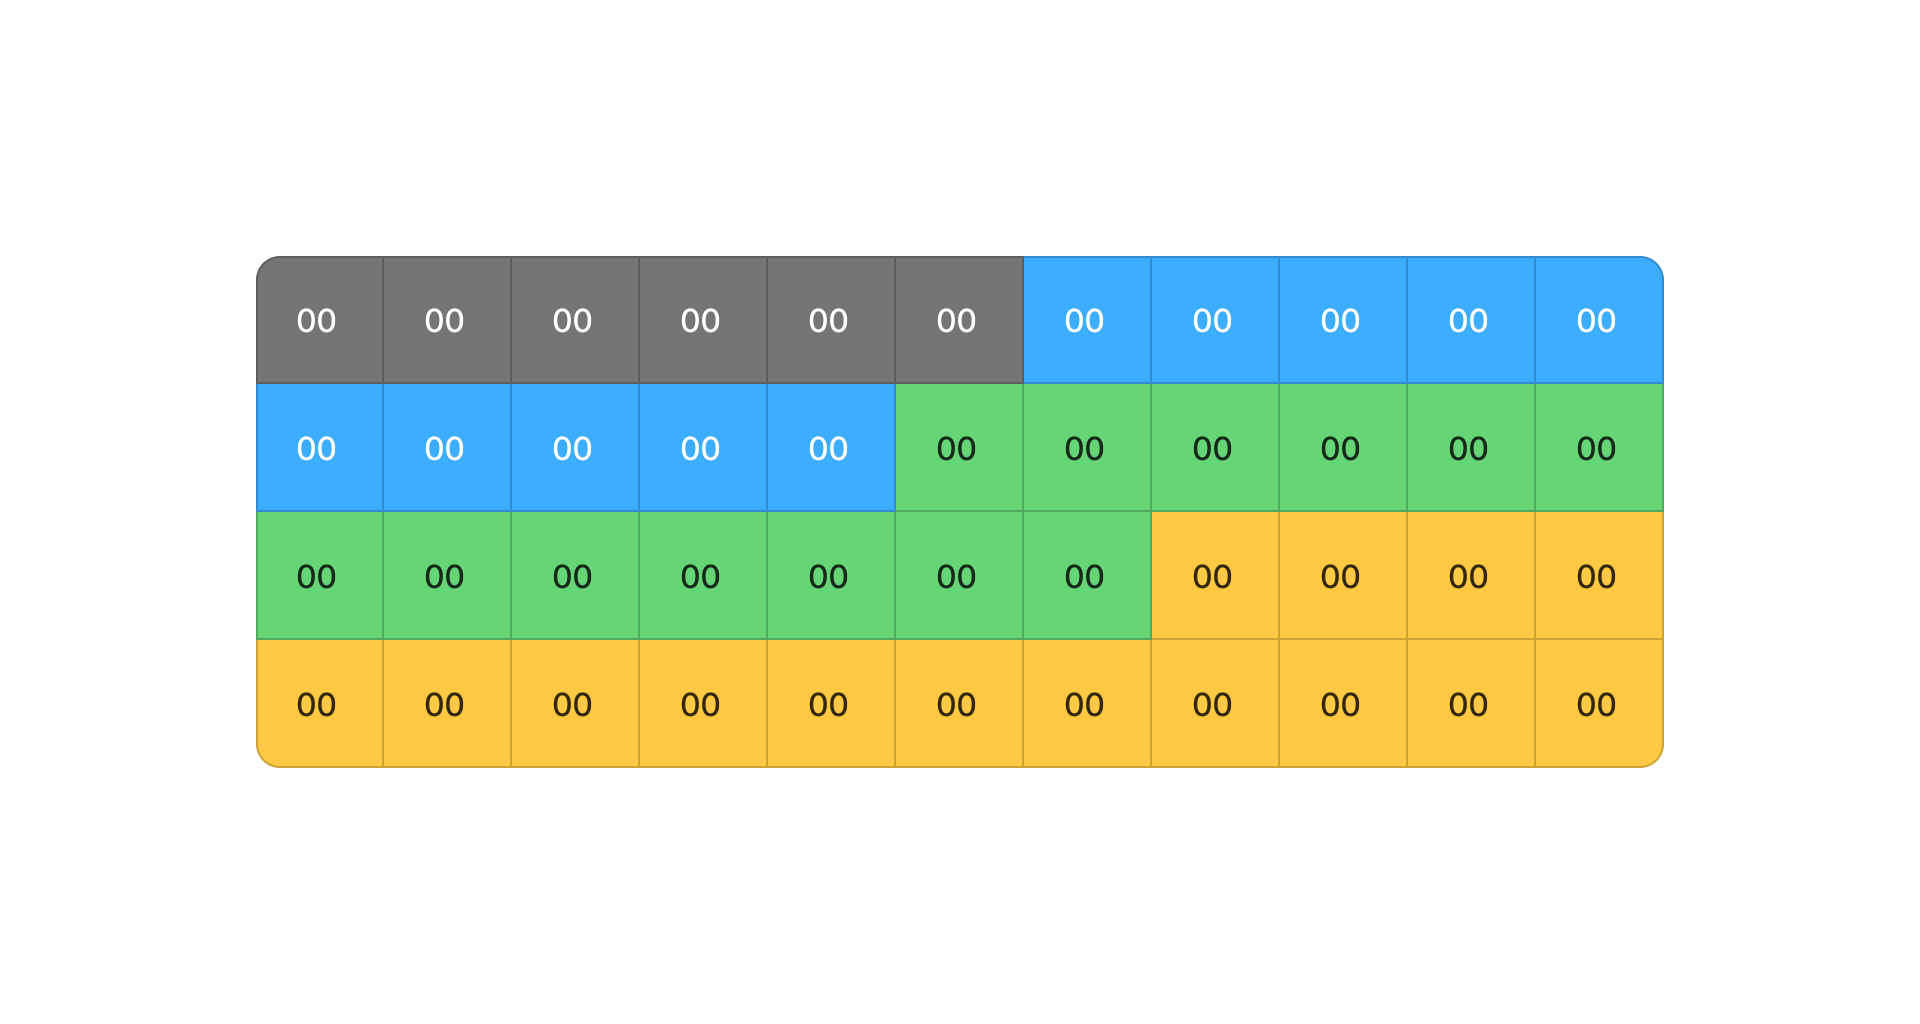
🪆 Protocols are Nested (Like Russian Dolls)
A network packet is structured as a series of encapsulated layers: each layer contains a protocol that encapsulates the next.
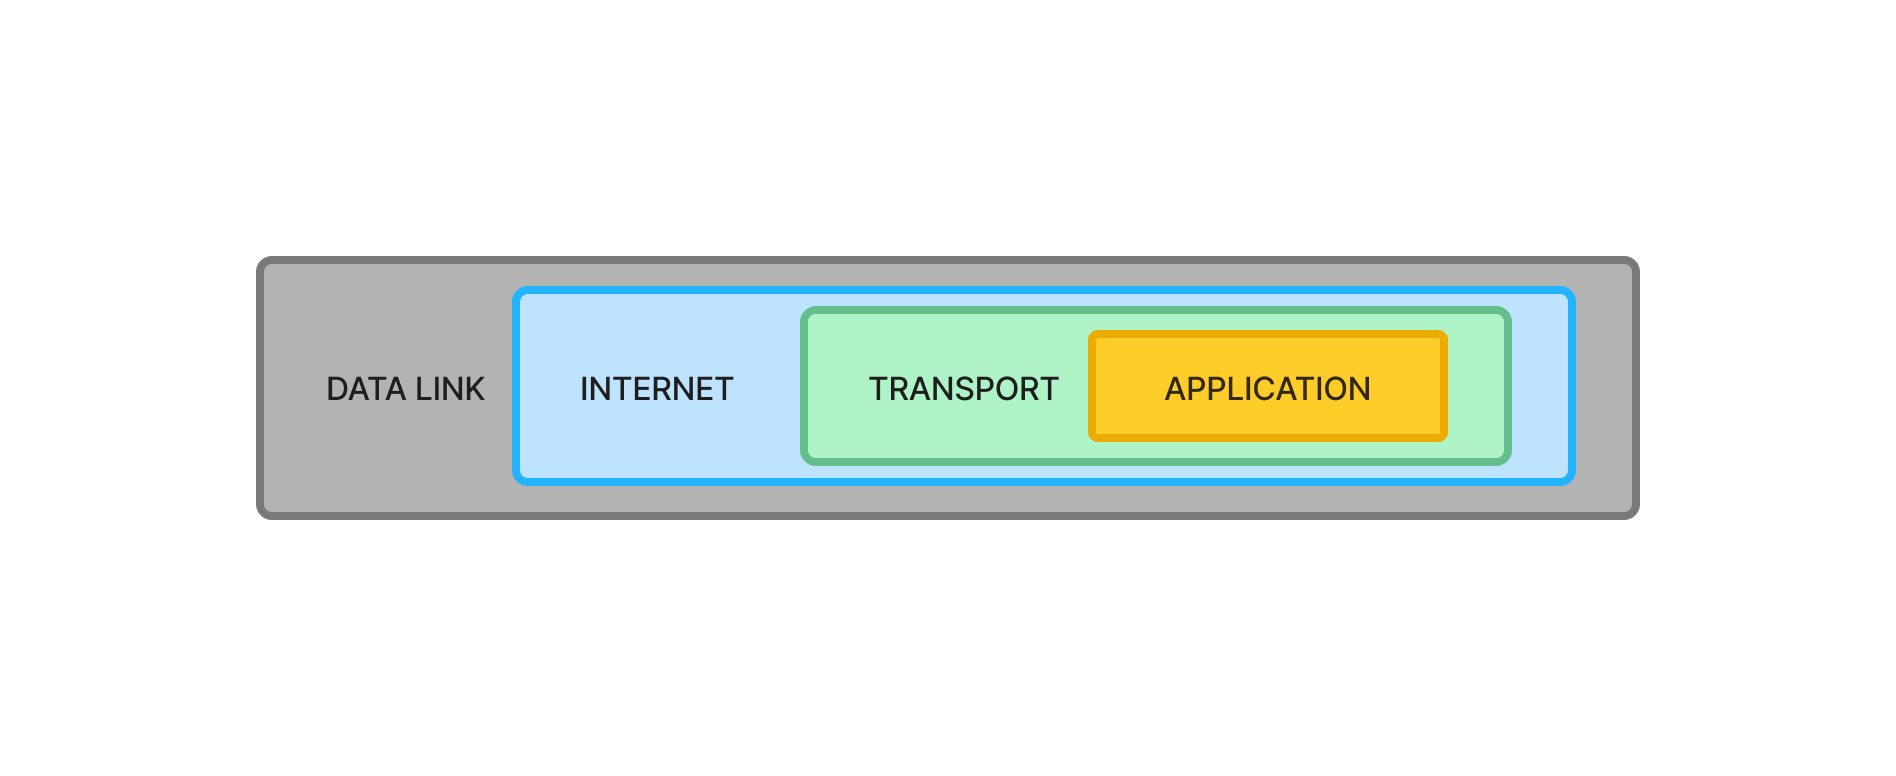
PacketFlow Layered Structure
Once parsed, a packet is structured into four layers, following the OSI model:
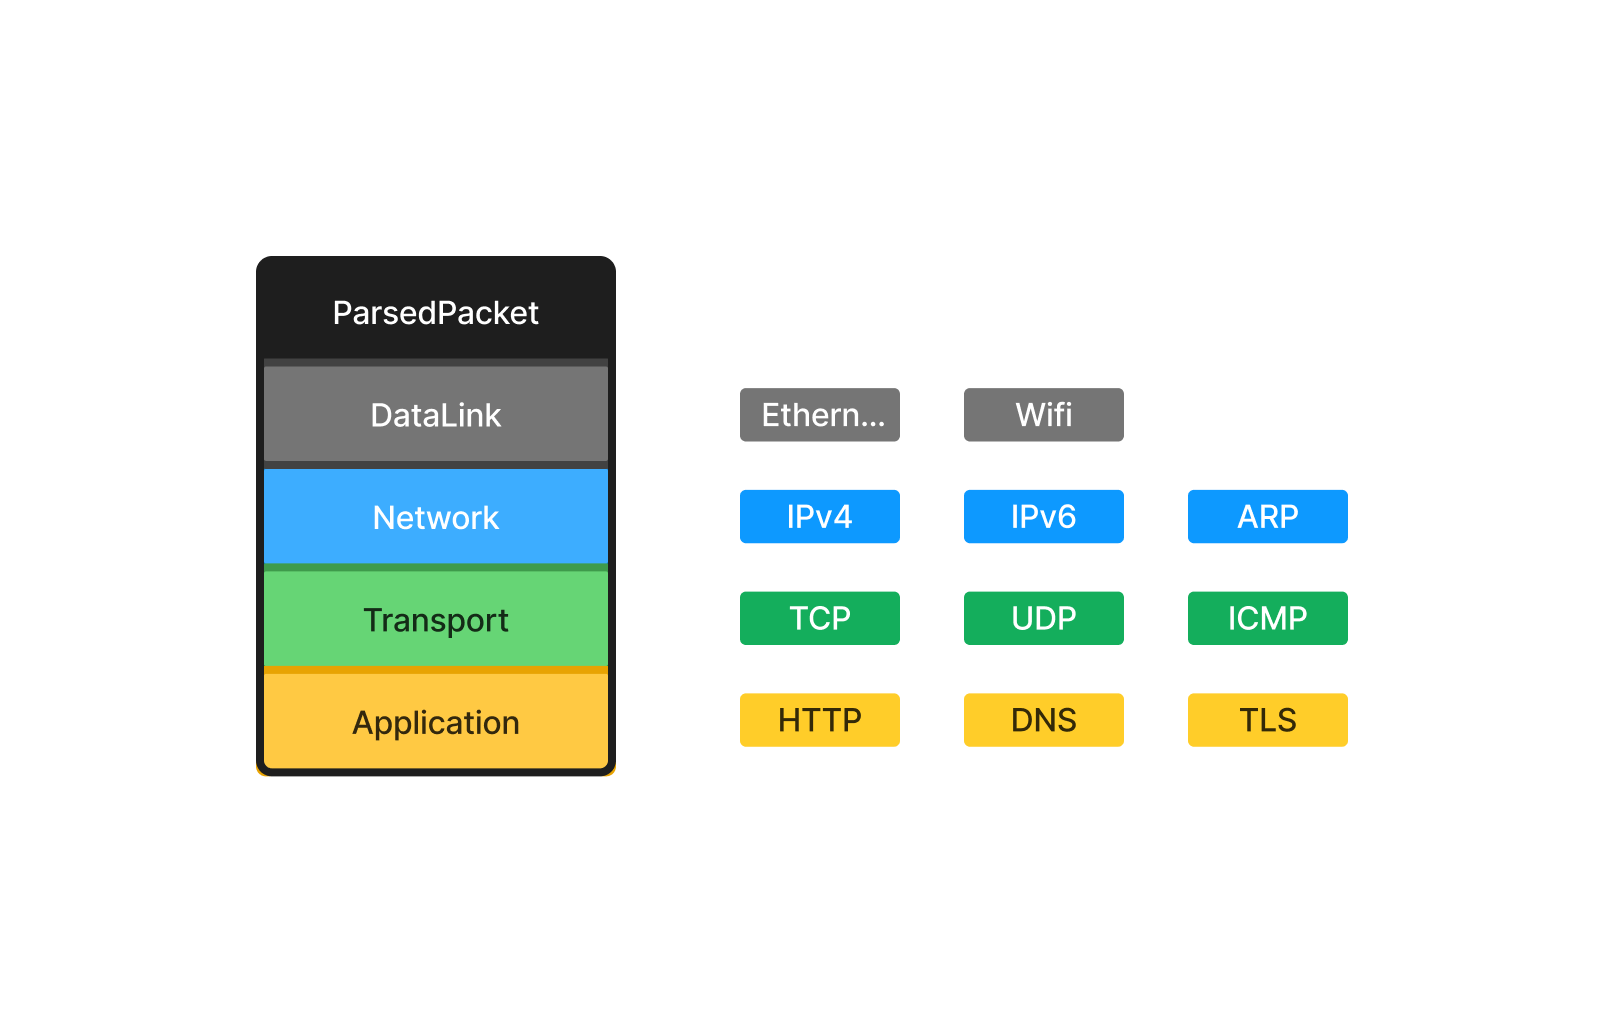
The diagrams in this book still say
ParsedPacket: that was the name of the struct when they were drawn. The struct is now calledPacketFlow.
The Data Link Layer is always present, while the others depend on the packet type.
Here is the actual struct:
#![allow(unused)]
fn main() {
pub struct PacketFlow<'a> {
    /// Link layer (mandatory), tagged with its canonical LINKTYPE.
    pub data_link: LinkLayer<'a>,
    /// Internet layer (optional).
    pub internet: Option<Internet<'a>>,
    /// Transport layer (optional).
    pub transport: Option<Transport<'a>>,
    /// Application layer (optional, best-effort).
    pub application: Option<Application>,
    /// Encapsulated packet, when this flow is a tunnel (CAPWAP, GRE, VXLAN...).
    pub inner: Option<Box<PacketFlow<'a>>>,
    /// Present when a recognized layer carried invalid bytes.
    pub corrupted: Option<CorruptedLayer>,
}
}
Two fields were not in the original design and deserve a word:
inner: some packets carry a whole other packet inside their payload. When a tunnel is recognized, its name goes intoapplicationand the encapsulated packet is parsed recursively intoinner. See the tunnels chapter.corrupted: a layer that was recognized (the EtherType said IPv4, the IP header said TCP) but whose bytes are invalid does not fail the whole parse. The layers above it are kept, the problem is reported here. See getting started.
🔗 How Layers Interact with Addresses and Entry/Exit Points
Each layer contains specific information to identify source and destination addresses.
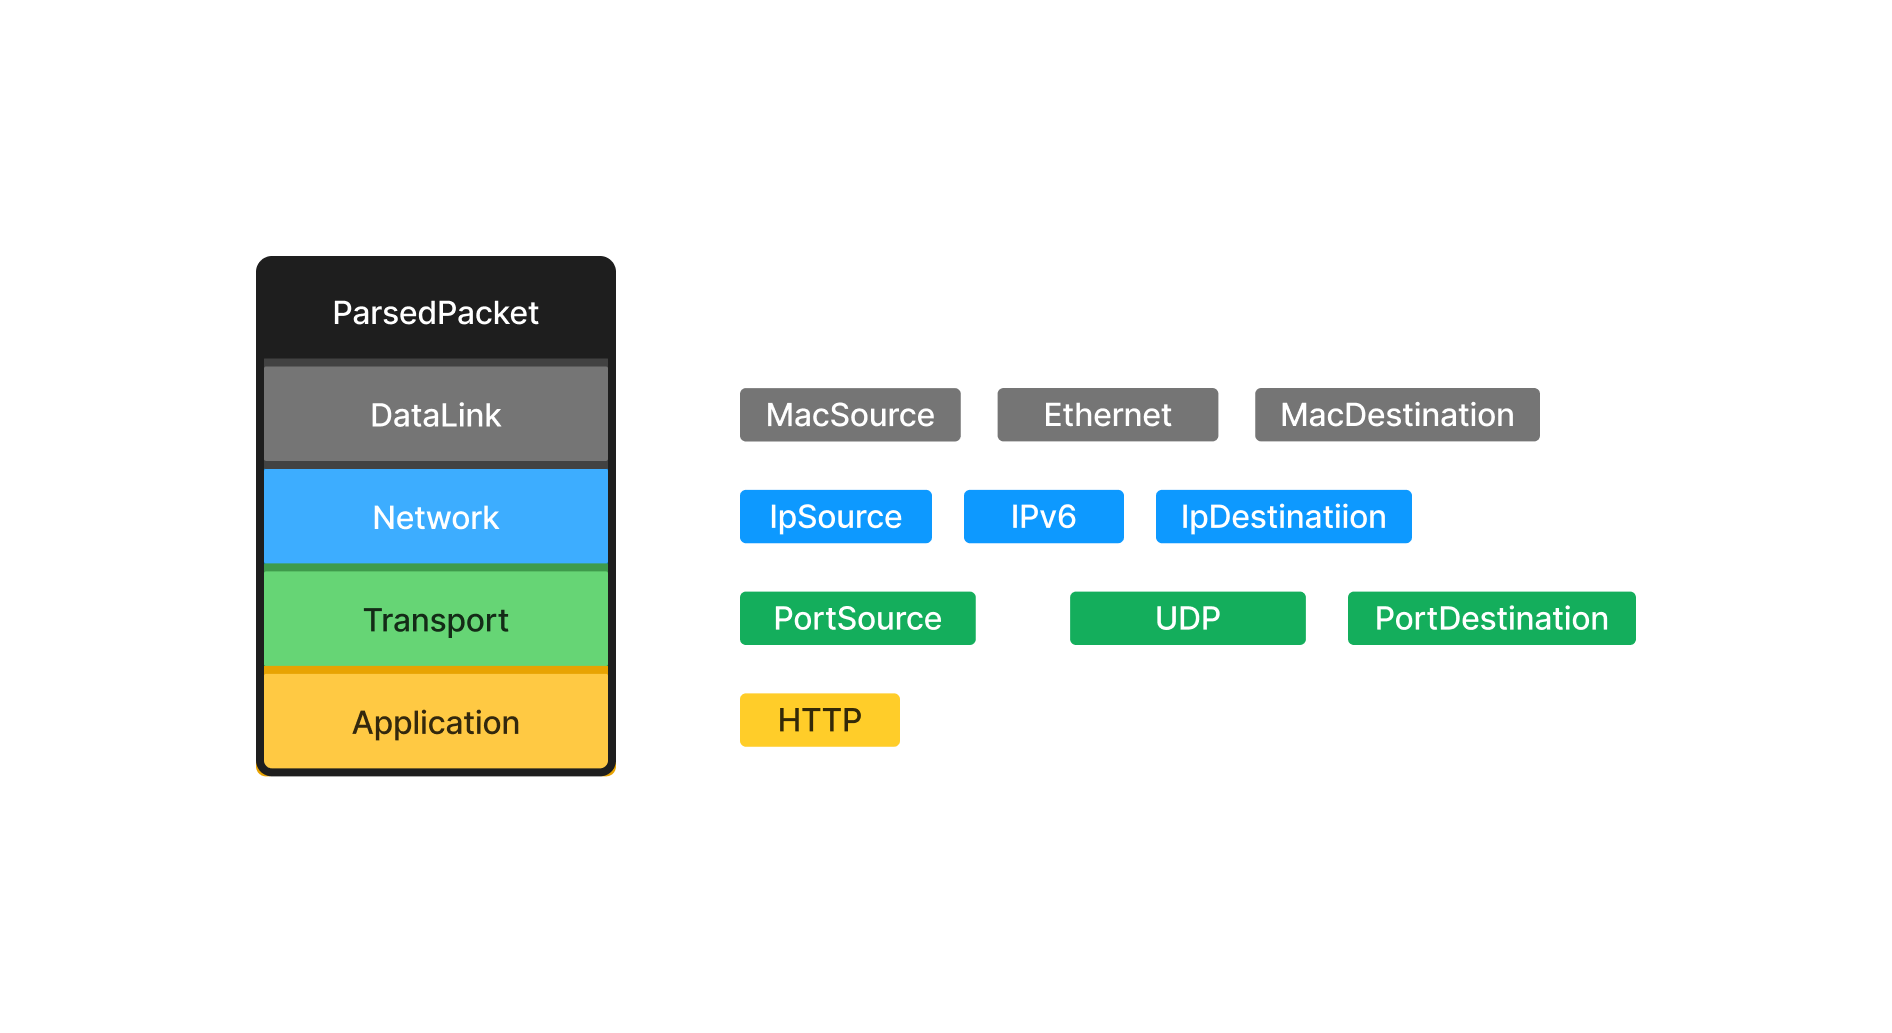
This is what I call the flow identity: MAC addresses, IP addresses, protocols, ports. PacketFlow implements PartialEq, Eq and Hash on this identity only, not on the raw bytes: payloads are deliberately ignored. Two packets of the same conversation carrying different data compare equal and hash identically, which is exactly what you want to build a flow table with a HashMap<PacketFlowOwned, Stats>.
🧐 Detailed Breakdown of Parsed Structures
Each layer has its own structure with unique fields.
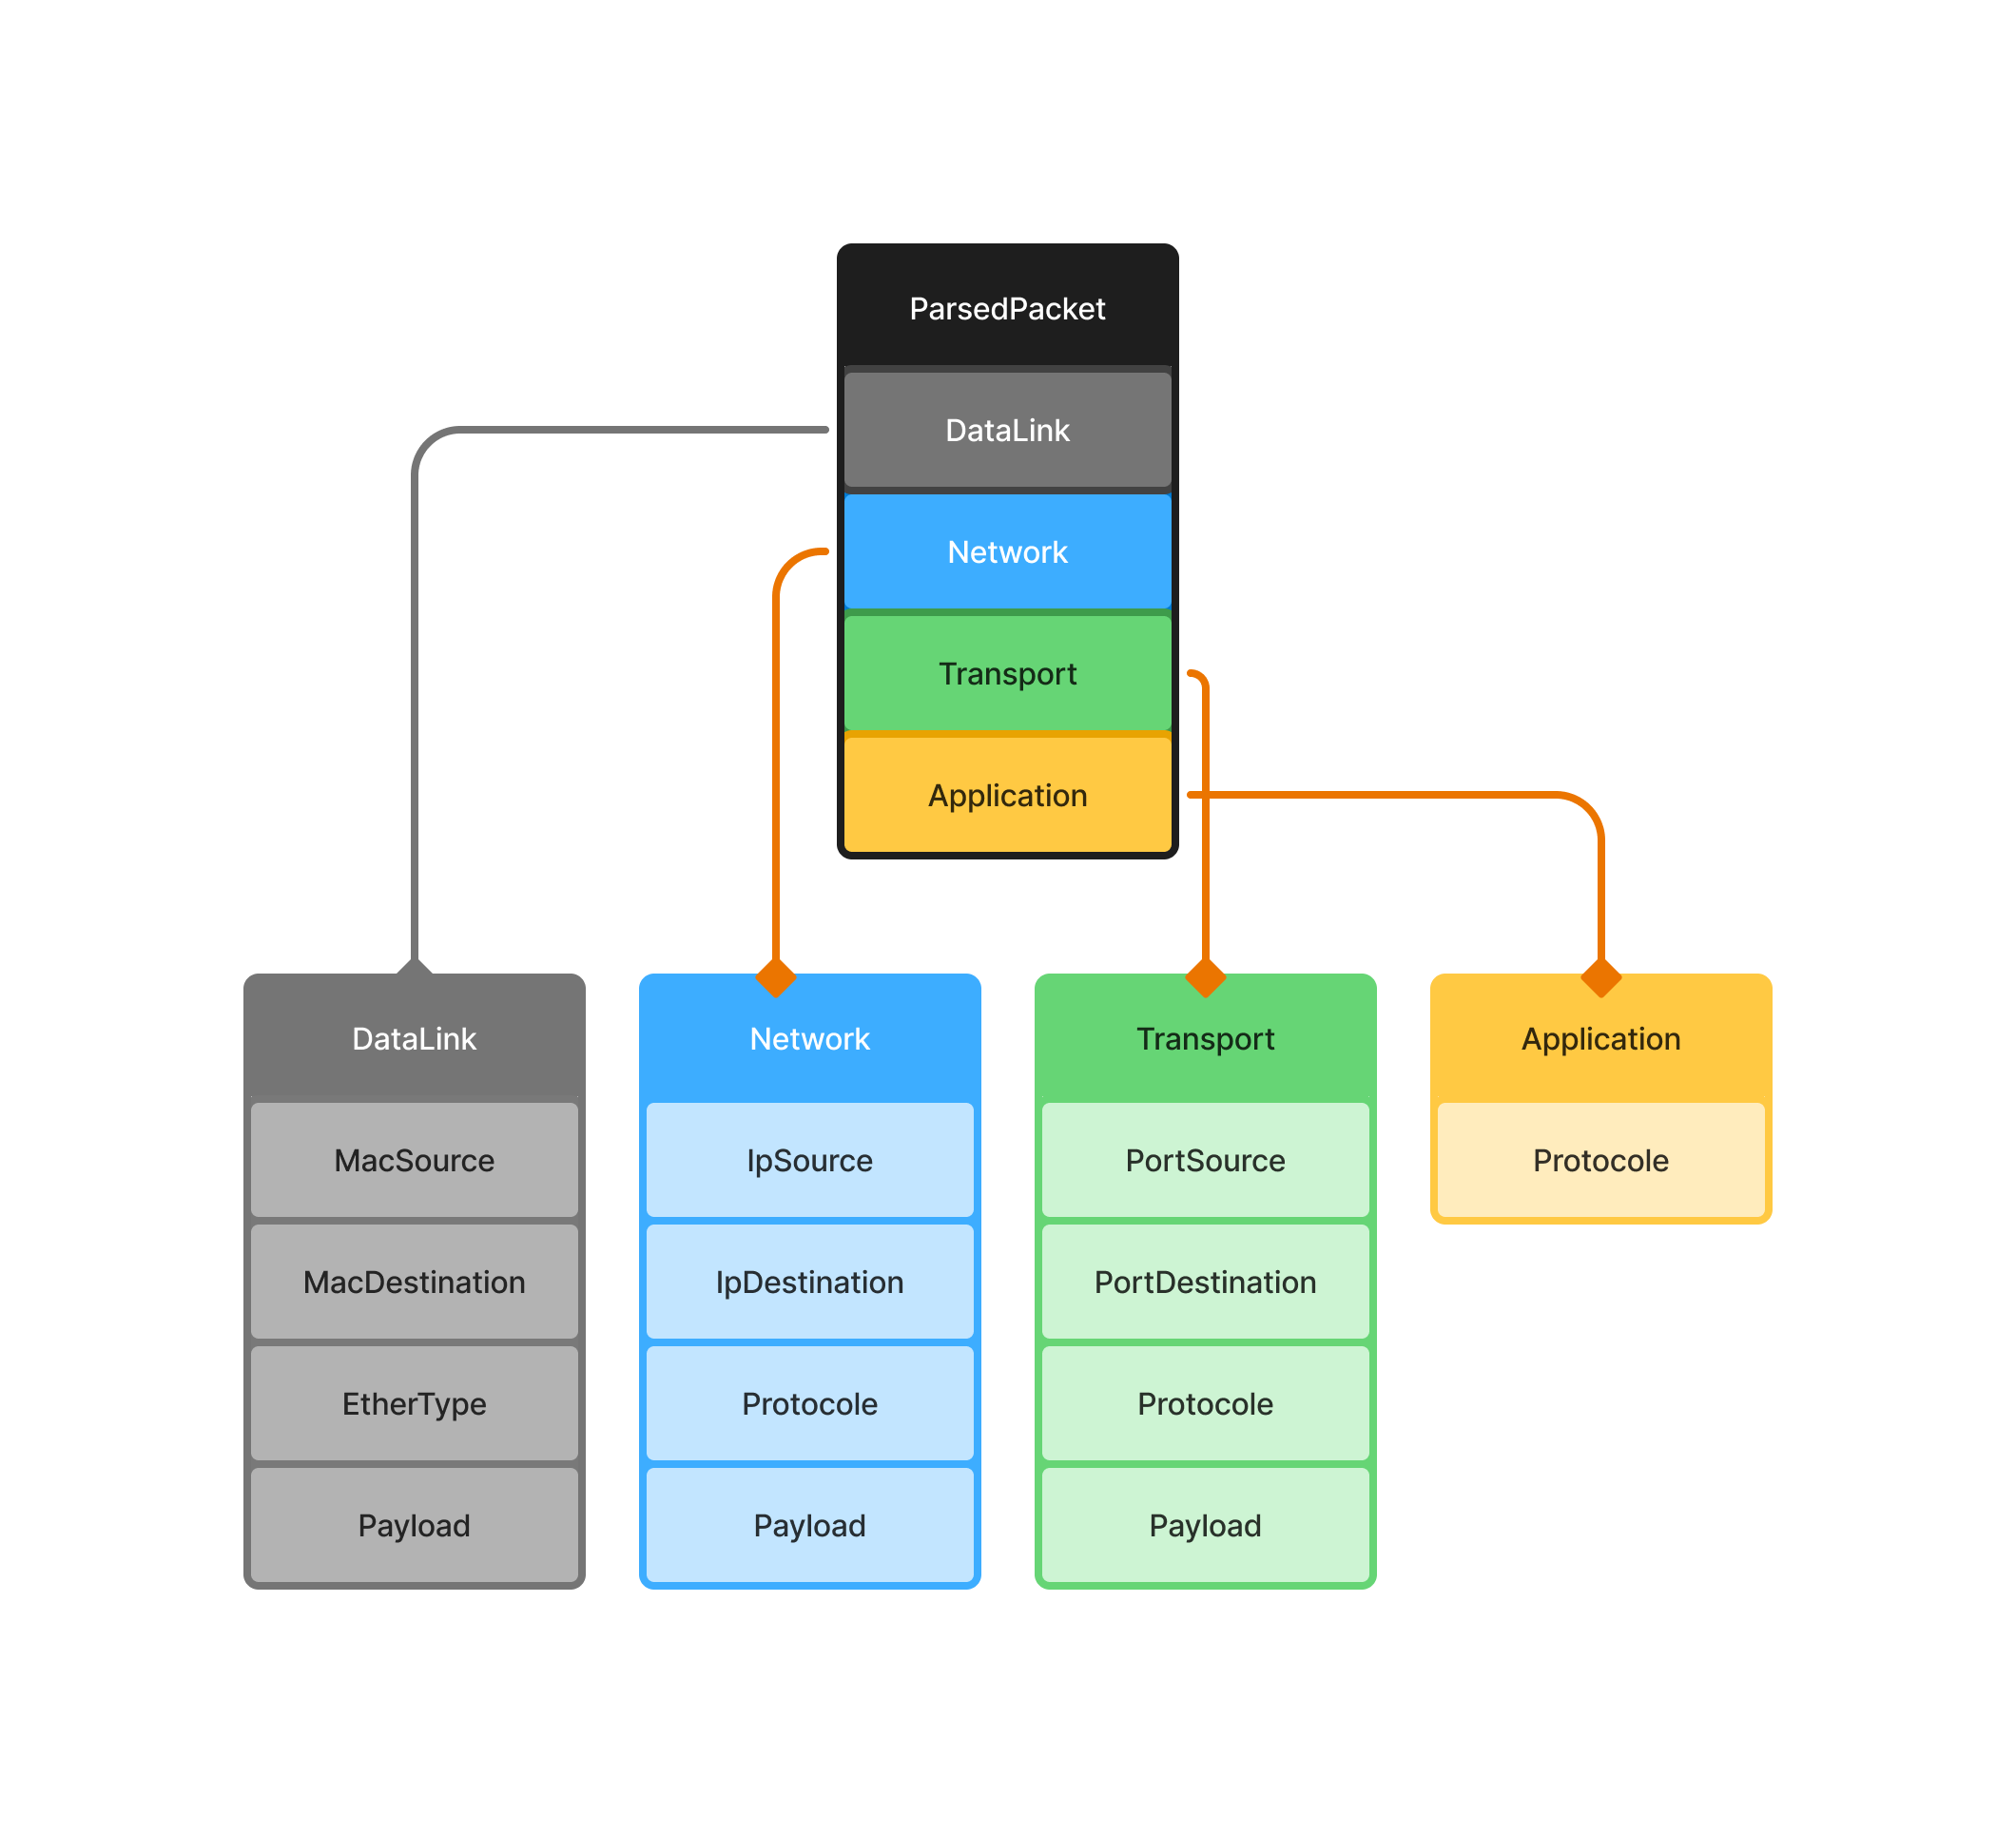
Each layer exposes two levels of information:
- the flattened summary you see in the diagram (
source,destination,protocol_name,source_port...), which defines the identity of the layer and is what gets serialized; - a
detailsfield (InternetDetails,TransportDetails) holding the full parsed header (Ipv4Packet,TcpPacket,IcmpPacket...), so you never need to re-parse the payload to reach the TTL, the DSCP or the TCP flags.detailsis ignored by equality, hashing and serialization.
The data link layer is the exception: LinkLayer is format-neutral (Ethernet, RAW IP, Linux cooked capture...), and the format-specific view is reached through as_ethernet(), as_linux_sll(), etc. See the data link chapter.
Parsing Strategy Based on Payloads
Parsing is determined by the payloads extracted at each stage.
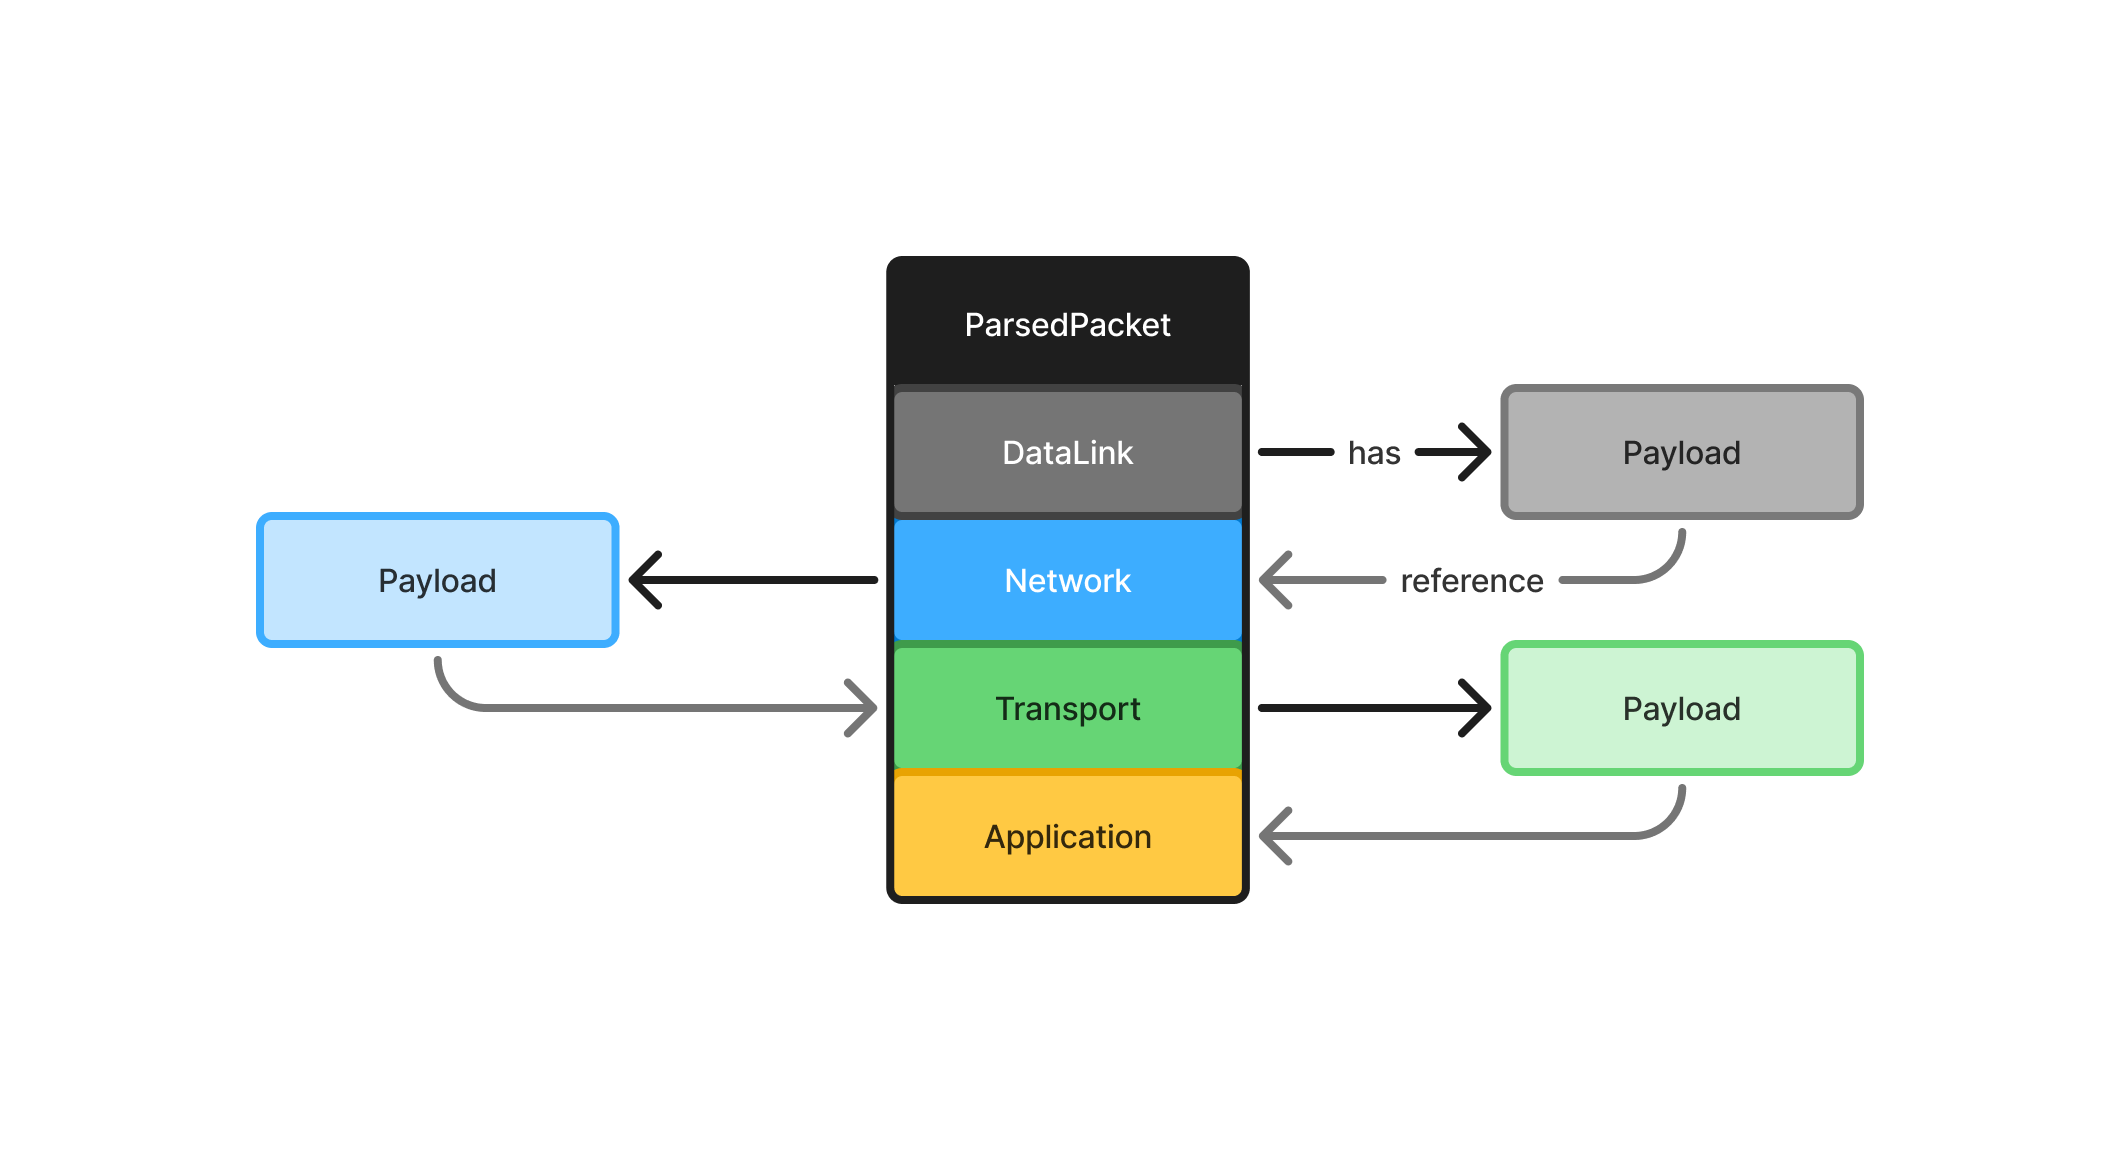
The pipeline is layered and progressive: each layer is parsed from the payload of the previous one, and each layer announces what the next one is.
| Step | Input | What tells us the next protocol | Output |
|---|---|---|---|
| Link | LINKTYPE + packet bytes | the caller (LINKTYPE) | LinkLayer + NetworkProtocol + L3 payload |
| Internet | NetworkProtocol + L3 payload | EtherType / SLL protocol field | Internet + payload_protocol + L4 payload |
| Transport | TransportProtocol + L4 payload | IP protocol number / next header | Transport + ports + L7 payload |
| Application | Transport (ports + payload) | content probes, guarded by transport and sometimes by port | Application { application_protocol } |
Independent Layer Parsing
Each layer must be parsed independently from the others.
We do not use information from one layer to decode another.
Why?
- Security: attackers can manipulate packet fields (e.g. changing port numbers).
- Flexibility: some protocols do not strictly follow conventional port assignments.
- Reliability: parsing should be based on raw data, not assumptions.
For example, we do not label an application-layer protocol based on the transport-layer port number alone.
Just because a packet has port 80 does not mean it contains HTTP: it could be anything.
The rule has one nuance, learned the hard way. Some protocols have a signature too weak to be recognized from their bytes alone: an FTP reply, an SMTP reply and an NNTP reply are byte-for-byte identical (220 text CRLF). For those, the standard port is used as a guard in addition to the content check, never instead of it: the label is only given when port and content agree. The application chapter details this table.
Data validation procedure
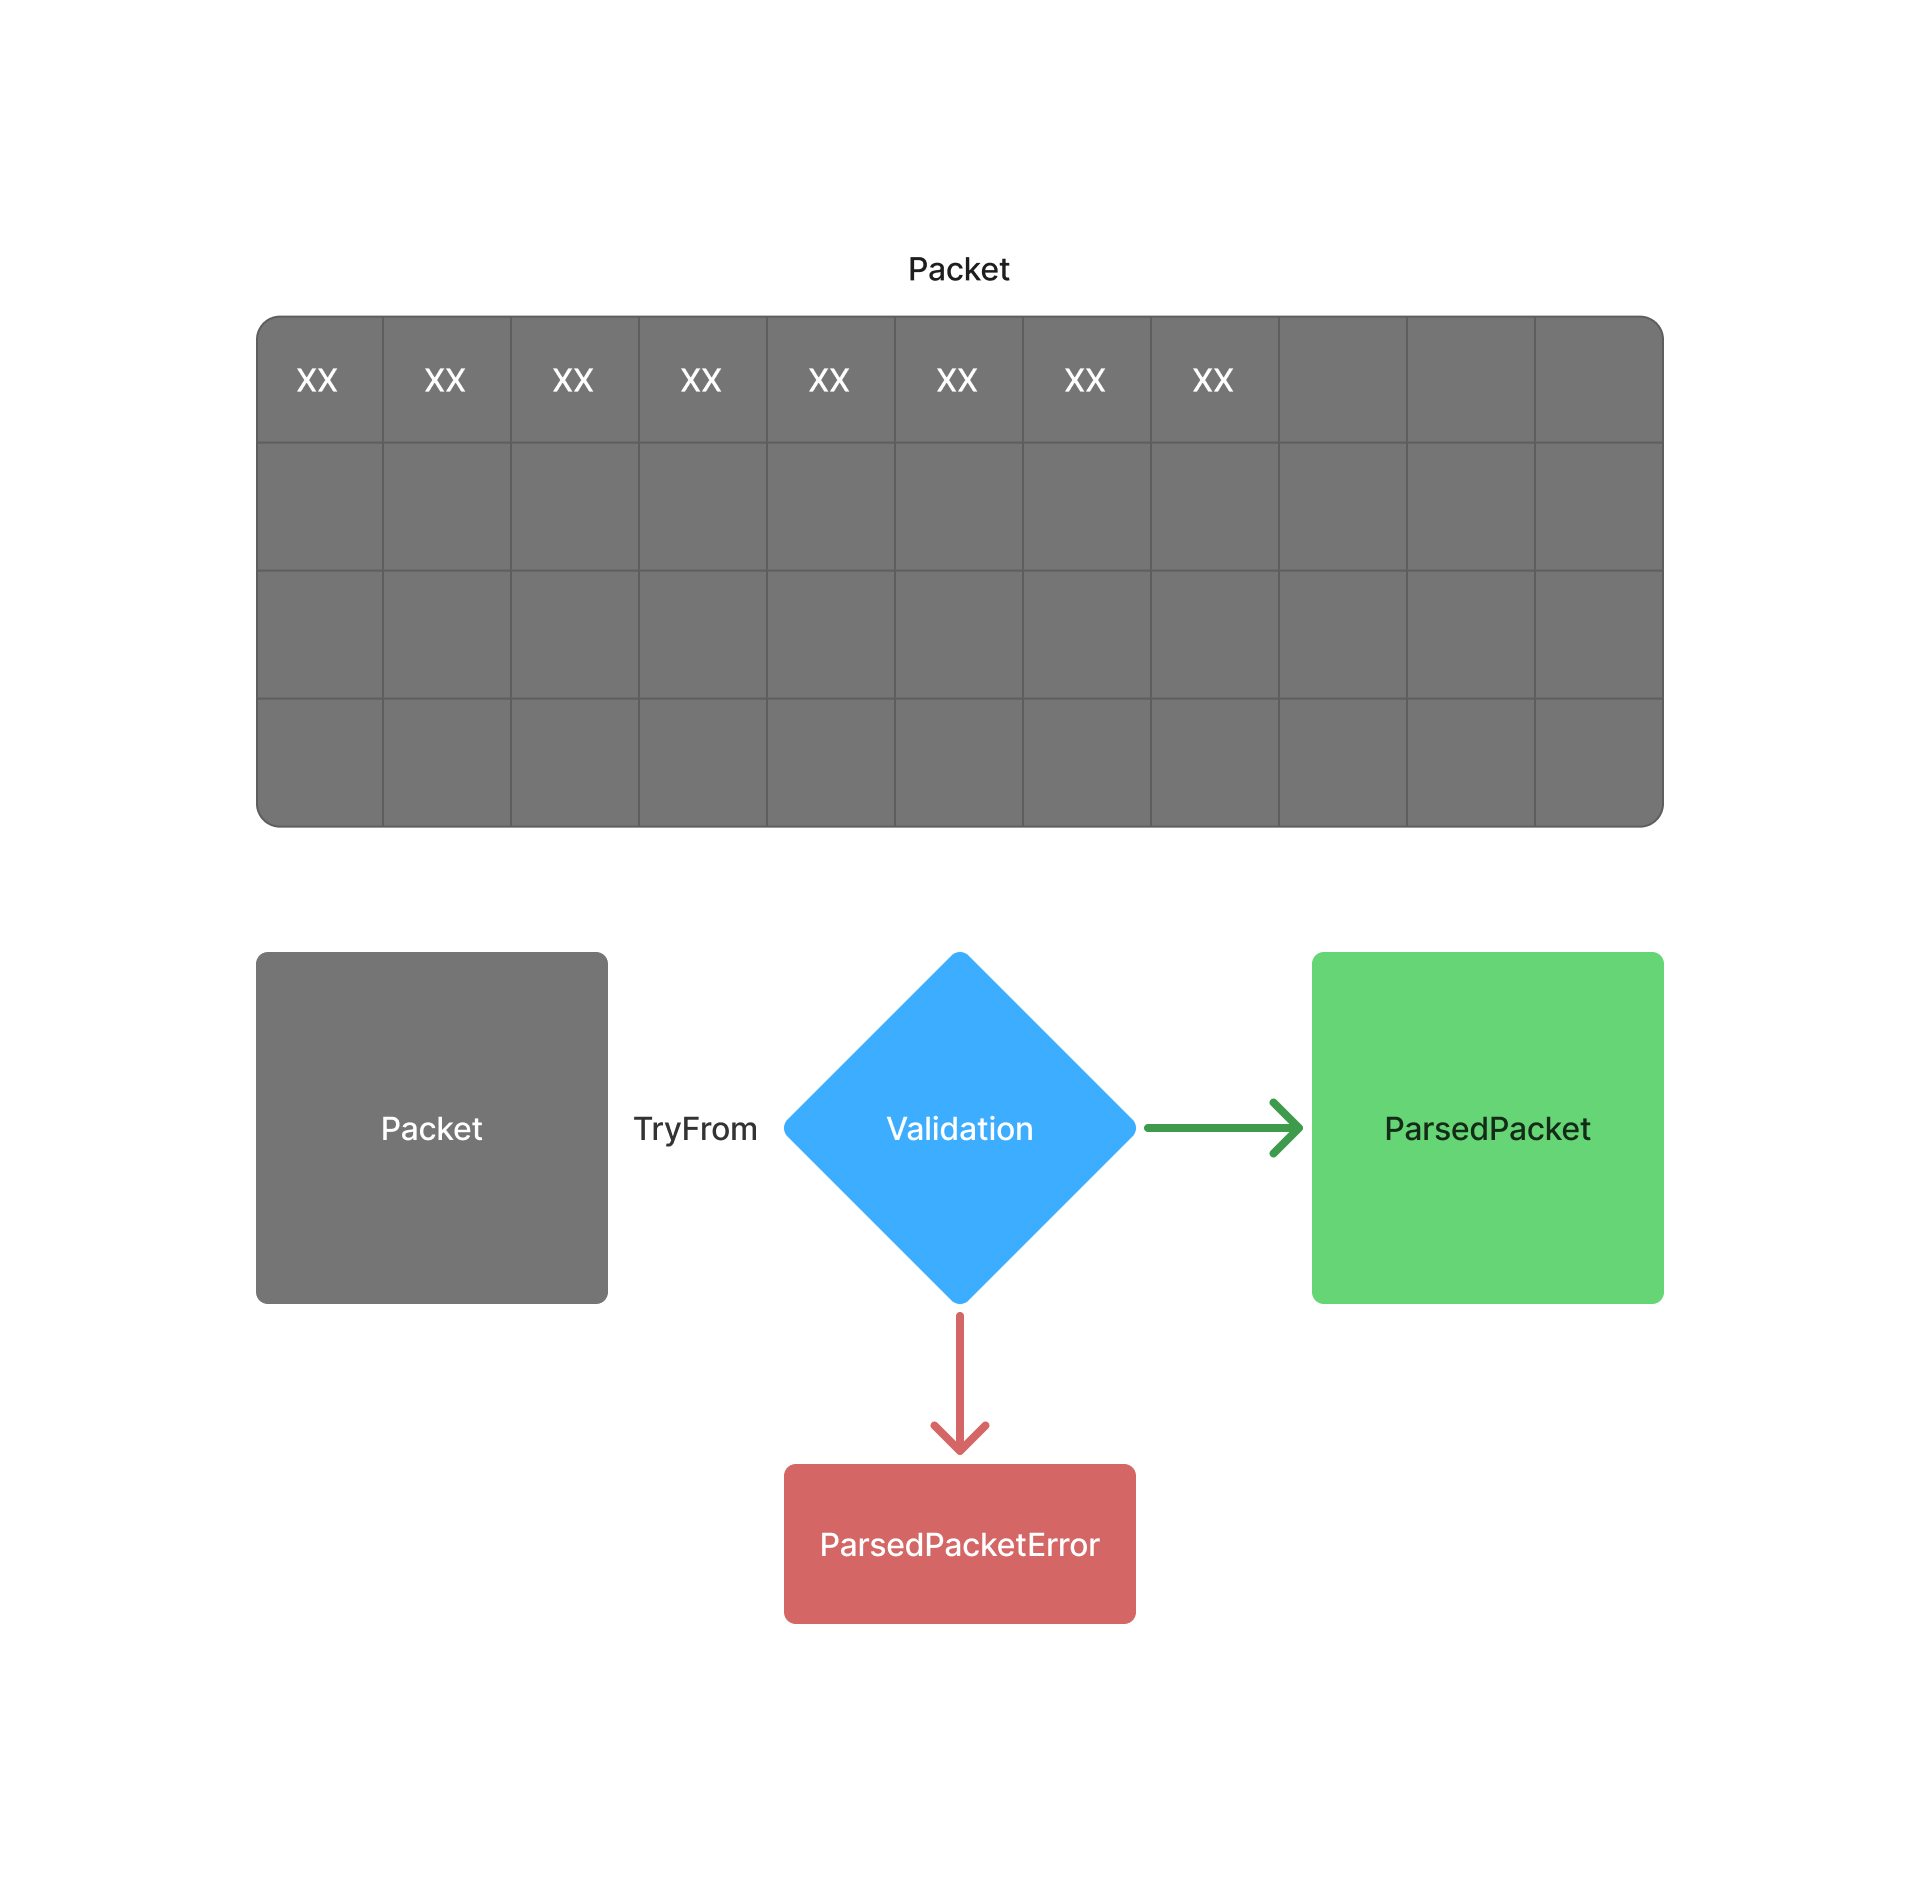
When we receive a packet, we use TryFrom to apply several validation steps to it.
If the validations succeed, the function returns a structured representation of the packet or a part of it.
If the validations fail, it returns a custom error, implemented using the thiserror crate.
In the diagram the error is called
ParsedPacketError. It is nowParseErrorfor the top-level API, and each layer and each protocol has its own error type (DataLinkError,Ipv4Error,TcpError,NtpPacketParseError...).
Every struct is a TryFrom<&[u8]>
This is the one rule of the crate. DataLink, Ipv4Packet, TcpPacket, DnsPacket, TlsPacket... all of them are built the same way:
#![allow(unused)]
fn main() {
impl<'a> TryFrom<&'a [u8]> for Ipv4Packet<'a> {
    type Error = Ipv4Error;

    fn try_from(data: &'a [u8]) -> Result<Self, Self::Error> {
        validate_ipv4_min_length(data)?;

        let version_ihl = data[0];
        validate_ipv4_version(version_ihl >> 4)?;

        let header_len = ((version_ihl & 0x0F) as usize) * 4;
        validate_ipv4_header_length(header_len)?;
        validate_ipv4_header_available(data.len(), header_len)?;

        let total_length = u16::from_be_bytes([data[2], data[3]]);
        validate_ipv4_total_length(total_length, header_len, data.len())?;

        // ... every remaining field is read with from_be_bytes ...

        Ok(Ipv4Packet { /* ... */, payload: &data[header_len..total_length as usize] })
    }
}
}
The TryFrom is a linear sequence, in wire order:
- a pre-check on the length, so that every index below is proven in-bounds;
- one check per constrained field, chained with
?: check the bytes of the field, place the value if it is valid, move on to the next field; - cross-field validations between values already extracted;
- build the struct with the validated values, and split header from payload.
As soon as a check fails, ? returns the typed error: the bytes are not this protocol.
Where the checks live
The parser file only chains the calls. The checks themselves live in a separate, crate-internal module, one file per protocol:
src/
  parse/     the TryFrom impls and the structs      (public)
  checks/    validate_* and extract_* functions       (crate-internal)
  errors/    one thiserror enum per protocol          (public)
Two forms of functions:
extract_*: verifies the bytes of one field and returns the typed value, ready to be placed in the struct (extract_stratum,extract_reference_idon the NTP side);validate_*: returnsResult<(), Error>for controls that produce no value: length pre-check, cross-field coherence (validate_ipv4_total_length,validate_datetime_ordering).
A field without any constraint (a raw counter, a free identifier) is read directly with from_be_bytes in the parser.
Typed errors
Errors carry the values that failed, never a bare string, so a consumer can match on them:
#![allow(unused)]
fn main() {
#[derive(Error, Debug)]
#[non_exhaustive]
pub enum TcpError {
    #[error("Packet too short to be a valid TCP header")]
    PacketTooShort,
    #[error("Invalid data offset: {0}")]
    InvalidDataOffset(u8),
    #[error("Invalid TCP flags {flags:#04x}: SYN and FIN are both set")]
    InvalidFlags { flags: u8 },
    #[error("TCP reserved bits are set: {bits:#05b}")]
    ReservedBitsSet { bits: u8 },
}
}
Errors nest with #[from]: Ipv4Error converts into InternetError, which converts into ParseError. Every error enum is #[non_exhaustive], so a new variant can be added in a minor version; a match on them needs a _ arm.
Structural corruption vs. semantic anomaly
Not every failed check means the same thing:
- structural: the bytes cannot be read as this protocol (truncated header, impossible length). The
TryFromreturnsErr, and in the pipeline the layer becomesNonewithcorrupted: Some(..); - semantic: the header reads fine but says something no conforming stack emits (TCP SYN+FIN, reserved bits set). The
TryFromreturnsOk; the anomaly is exposed byTcpPacket::anomaly(), and the pipeline keeps the layer while reporting it incorrupted. This is a classic scan signature: the ports must stay available for correlation.
Fail-closed below, fail-soft above
The two error paths of PacketFlow are asymmetric on purpose:
- the link layer is fail-closed: an unsupported LINKTYPE or a truncated link header returns
Err(ParseError). Without a valid link layer there is nothing trustworthy to build on; - everything above is fail-soft: an unsupported protocol leaves the layer
None, a corrupt one is reported incorrupted. Real-world traffic is full of protocols the crate does not decode, and a flow matrix must not lose the L2/L3 information because of an odd L4.
No panic on hostile bytes
A parser of hostile bytes must never bring its host down. What the crate does about it, precisely:
- Lints.
lib.rsenablesclippy::unwrap_used,clippy::expect_usedandclippy::panicas warnings outside of tests, and the CI runs clippy with-D warnings, which makes them blocking. The rare justified sites carry a motivated#[expect]. Test code is free tounwrap. - The indexing idiom.
data[0]aftervalidate_ipv4_min_length(data)is the pattern everywhere: index after an explicit length check. The lintsindexing_slicingandarithmetic_side_effectsare deliberately not enabled: with more than a thousand such accesses, they would flag every one of them. - Fuzzing. The absence of panic on these accesses is exercised by the fuzz targets under
fuzz/(parse_packetflow,parse_linktype,parse_dns,parse_giop,parse_quic,parse_s7comm,parse_cotp,parse_application), seeded with real frames and run nightly.
None of this is a proof. Lints catch the explicit panics, not an out-of-bounds index; fuzzing finds panics, it does not demonstrate their absence. What the crate can claim is that every parser follows the same length-checked discipline, that the tooling refuses the obvious deviations, and that the fuzzers have not found a panic on the published versions. The same honesty applies to the other properties described in this book: TryFrom and corrupted describe how the supported layers behave; a protocol the crate does not decode is simply None, and zero-copy holds for the L2/L3/L4 structs and most application parsers — a few (DNS, HTTP, SNMP, GIOP service contexts) allocate Vecs for lists whose length the packet dictates, always bounded first.
Now let's go layer by layer.
Data link
Parsing the Data Link Layer from a Raw Packet
Understanding how to parse the Data Link Layer from raw packets is a crucial step in network packet analysis. The Data Link Layer provides essential information such as MAC addresses, EtherType, and payload extraction. This section explains the approach I took, first for Ethernet, then for the other link formats a capture can contain.
🧩 Understanding the Ethernet Frame
The Data Link Layer is responsible for frame-level communication between devices on the same network segment. In an Ethernet frame, the structure is as follows:
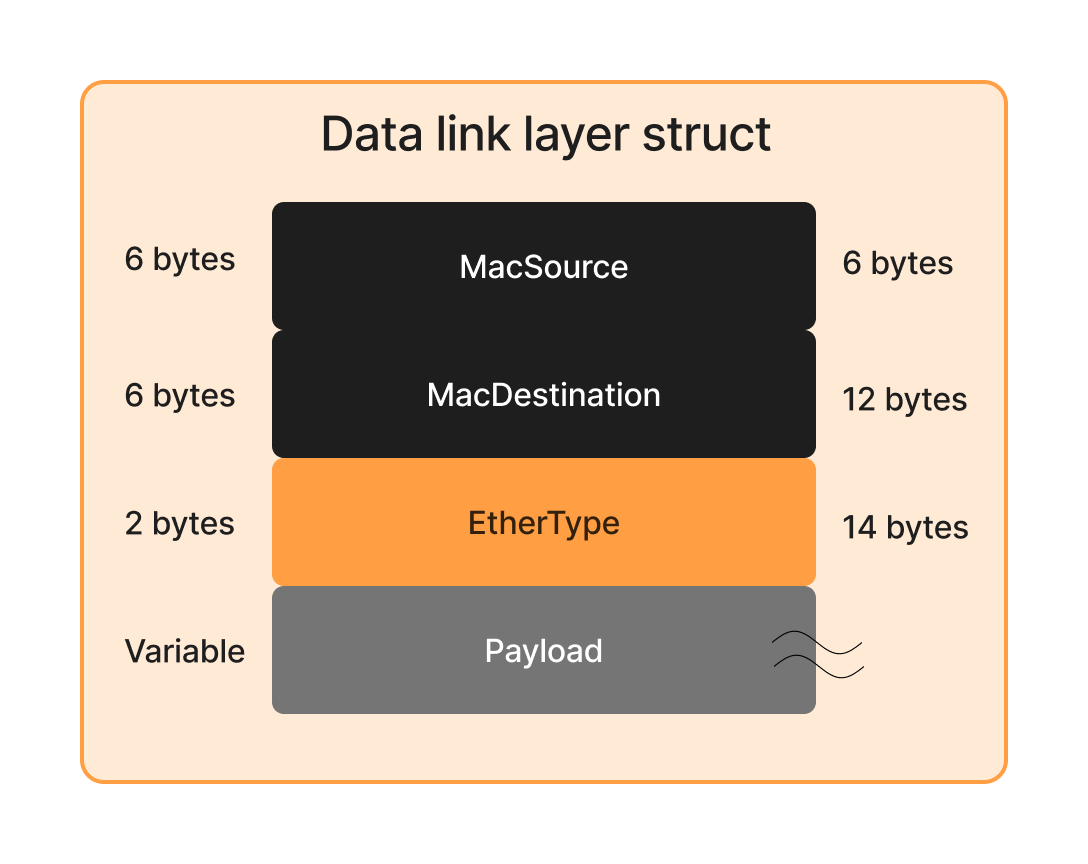
The main components are:
- Destination MAC Address (6 bytes) - the unique physical identifier of the receiving network hardware.
- Source MAC Address (6 bytes)
- EtherType (2 bytes) – determines the protocol encapsulated in the payload.
- Payload (variable length) – contains the encapsulated network-layer packet (IPv4, ARP, etc.).
Breaking Down the MAC Address Structure
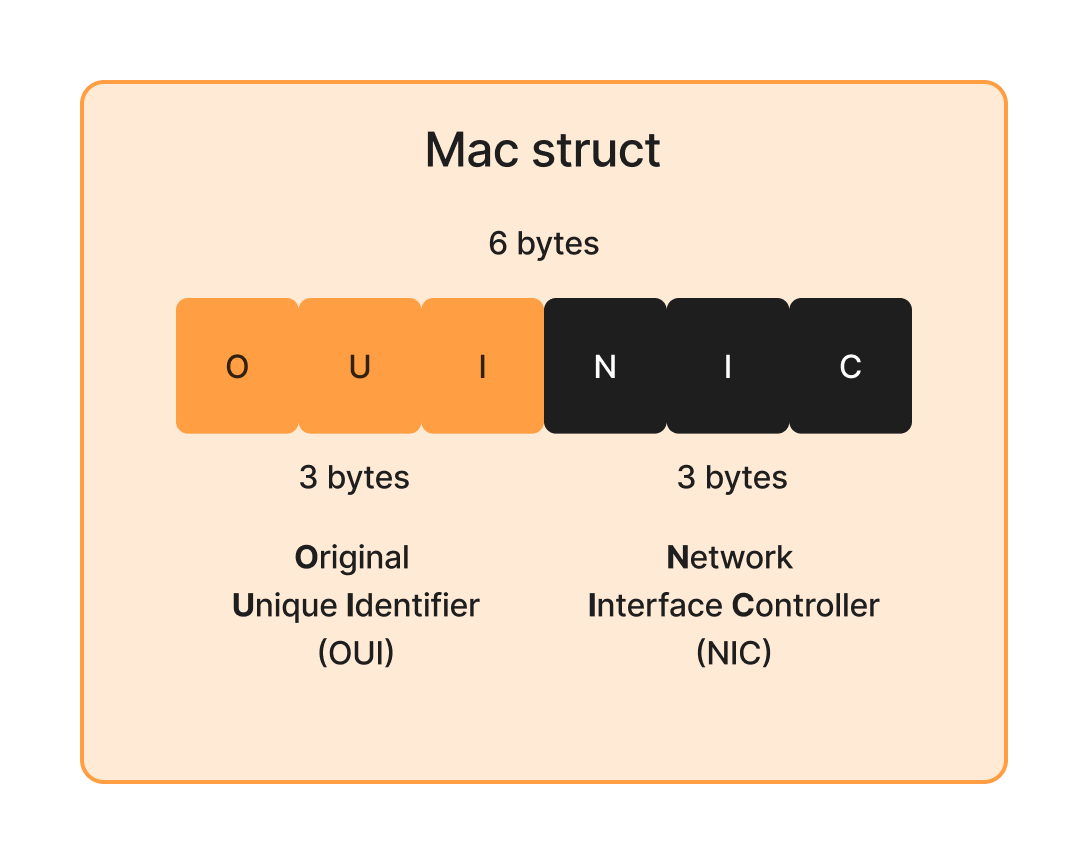
To parse MAC addresses correctly, we need to ensure that:
- They are always 6 bytes long.
- They are formatted properly for readability.
- We extract Organizationally Unique Identifiers (OUI) to identify the manufacturer.
MAC Address Structure:
#![allow(unused)]
fn main() {
pub struct MacAddress(pub [u8; 6]);

impl MacAddress {
    pub const fn is_broadcast(&self) -> bool;
    pub const fn is_multicast(&self) -> bool;
    pub const fn is_unicast(&self) -> bool;
    /// "2c:fd:a1:3c:4d:5e (ASUSTek)" when the OUI is known.
    pub fn display_with_oui(&self) -> String;
    pub fn get_oui(&self) -> Oui;
}
}
The OUI table is embedded in the crate: no file to load, no network lookup.
Breaking Down the EtherType Field
The EtherType is a 2-byte field that defines the type of payload carried by the frame.
📌 Key Considerations:
- Extract the 2-byte big-endian value.
- Map well-known EtherTypes (IPv4, IPv6, ARP, etc.).
- Allow handling of unknown protocols without failure:
Ethertype(pub u16)is a plain newtype, an unknown value is preserved, andstatic_name()returnsNonefor it.
📌 Example of Well-Known EtherTypes:
| EtherType (Hex) | Protocol |
|---|---|
0x0800 | IPv4 |
0x86DD | IPv6 |
0x0806 | ARP |
0x8892 | Profinet |
0x88CC | LLDP |
0x8100 | VLAN tag (802.1Q) |
0x88A8 / 0x9100 | Service tag (802.1ad / legacy QinQ) |
VLAN tags
When the EtherType is a TPID (0x8100, 0x88A8 or 0x9100), the next 4 bytes are a VLAN tag (TCI + the following EtherType), and that EtherType may itself be a TPID: 802.1ad puts an S-tag in front of the C-tag, and some equipment stacks two 0x8100. The parser consumes the whole stack so that ethertype and payload always describe the real layer 3:
#![allow(unused)]
fn main() {
pub struct DataLink<'a> {
    pub destination_mac: MacAddress,
    pub source_mac: MacAddress,
    /// The innermost tag (the customer VLAN), if any.
    pub vlan: Option<VlanTag>,
    /// The whole stack, outermost first (S-tag then C-tag).
    pub vlan_stack: VlanStack<'a>,
    /// The real layer-3 EtherType, after the tags.
    pub ethertype: Ethertype,
    pub payload: &'a [u8],
}

pub struct VlanTag {
    pub id: u16,      // VLAN identifier (12 bits)
    pub pcp: u8,      // priority code point (3 bits)
    pub dei: bool,    // drop eligible indicator
    pub inner_ethertype: Ethertype,
}
}
vlan_stack.outer() gives the S-VLAN, vlan_stack.iter() walks the stack from outer to inner. The untagged case is the hot path and stays a straight line; the stack is unrolled in a separate function.
📌 Steps Taken to Parse the Ethernet Frame
To correctly extract this information, I followed these key steps:
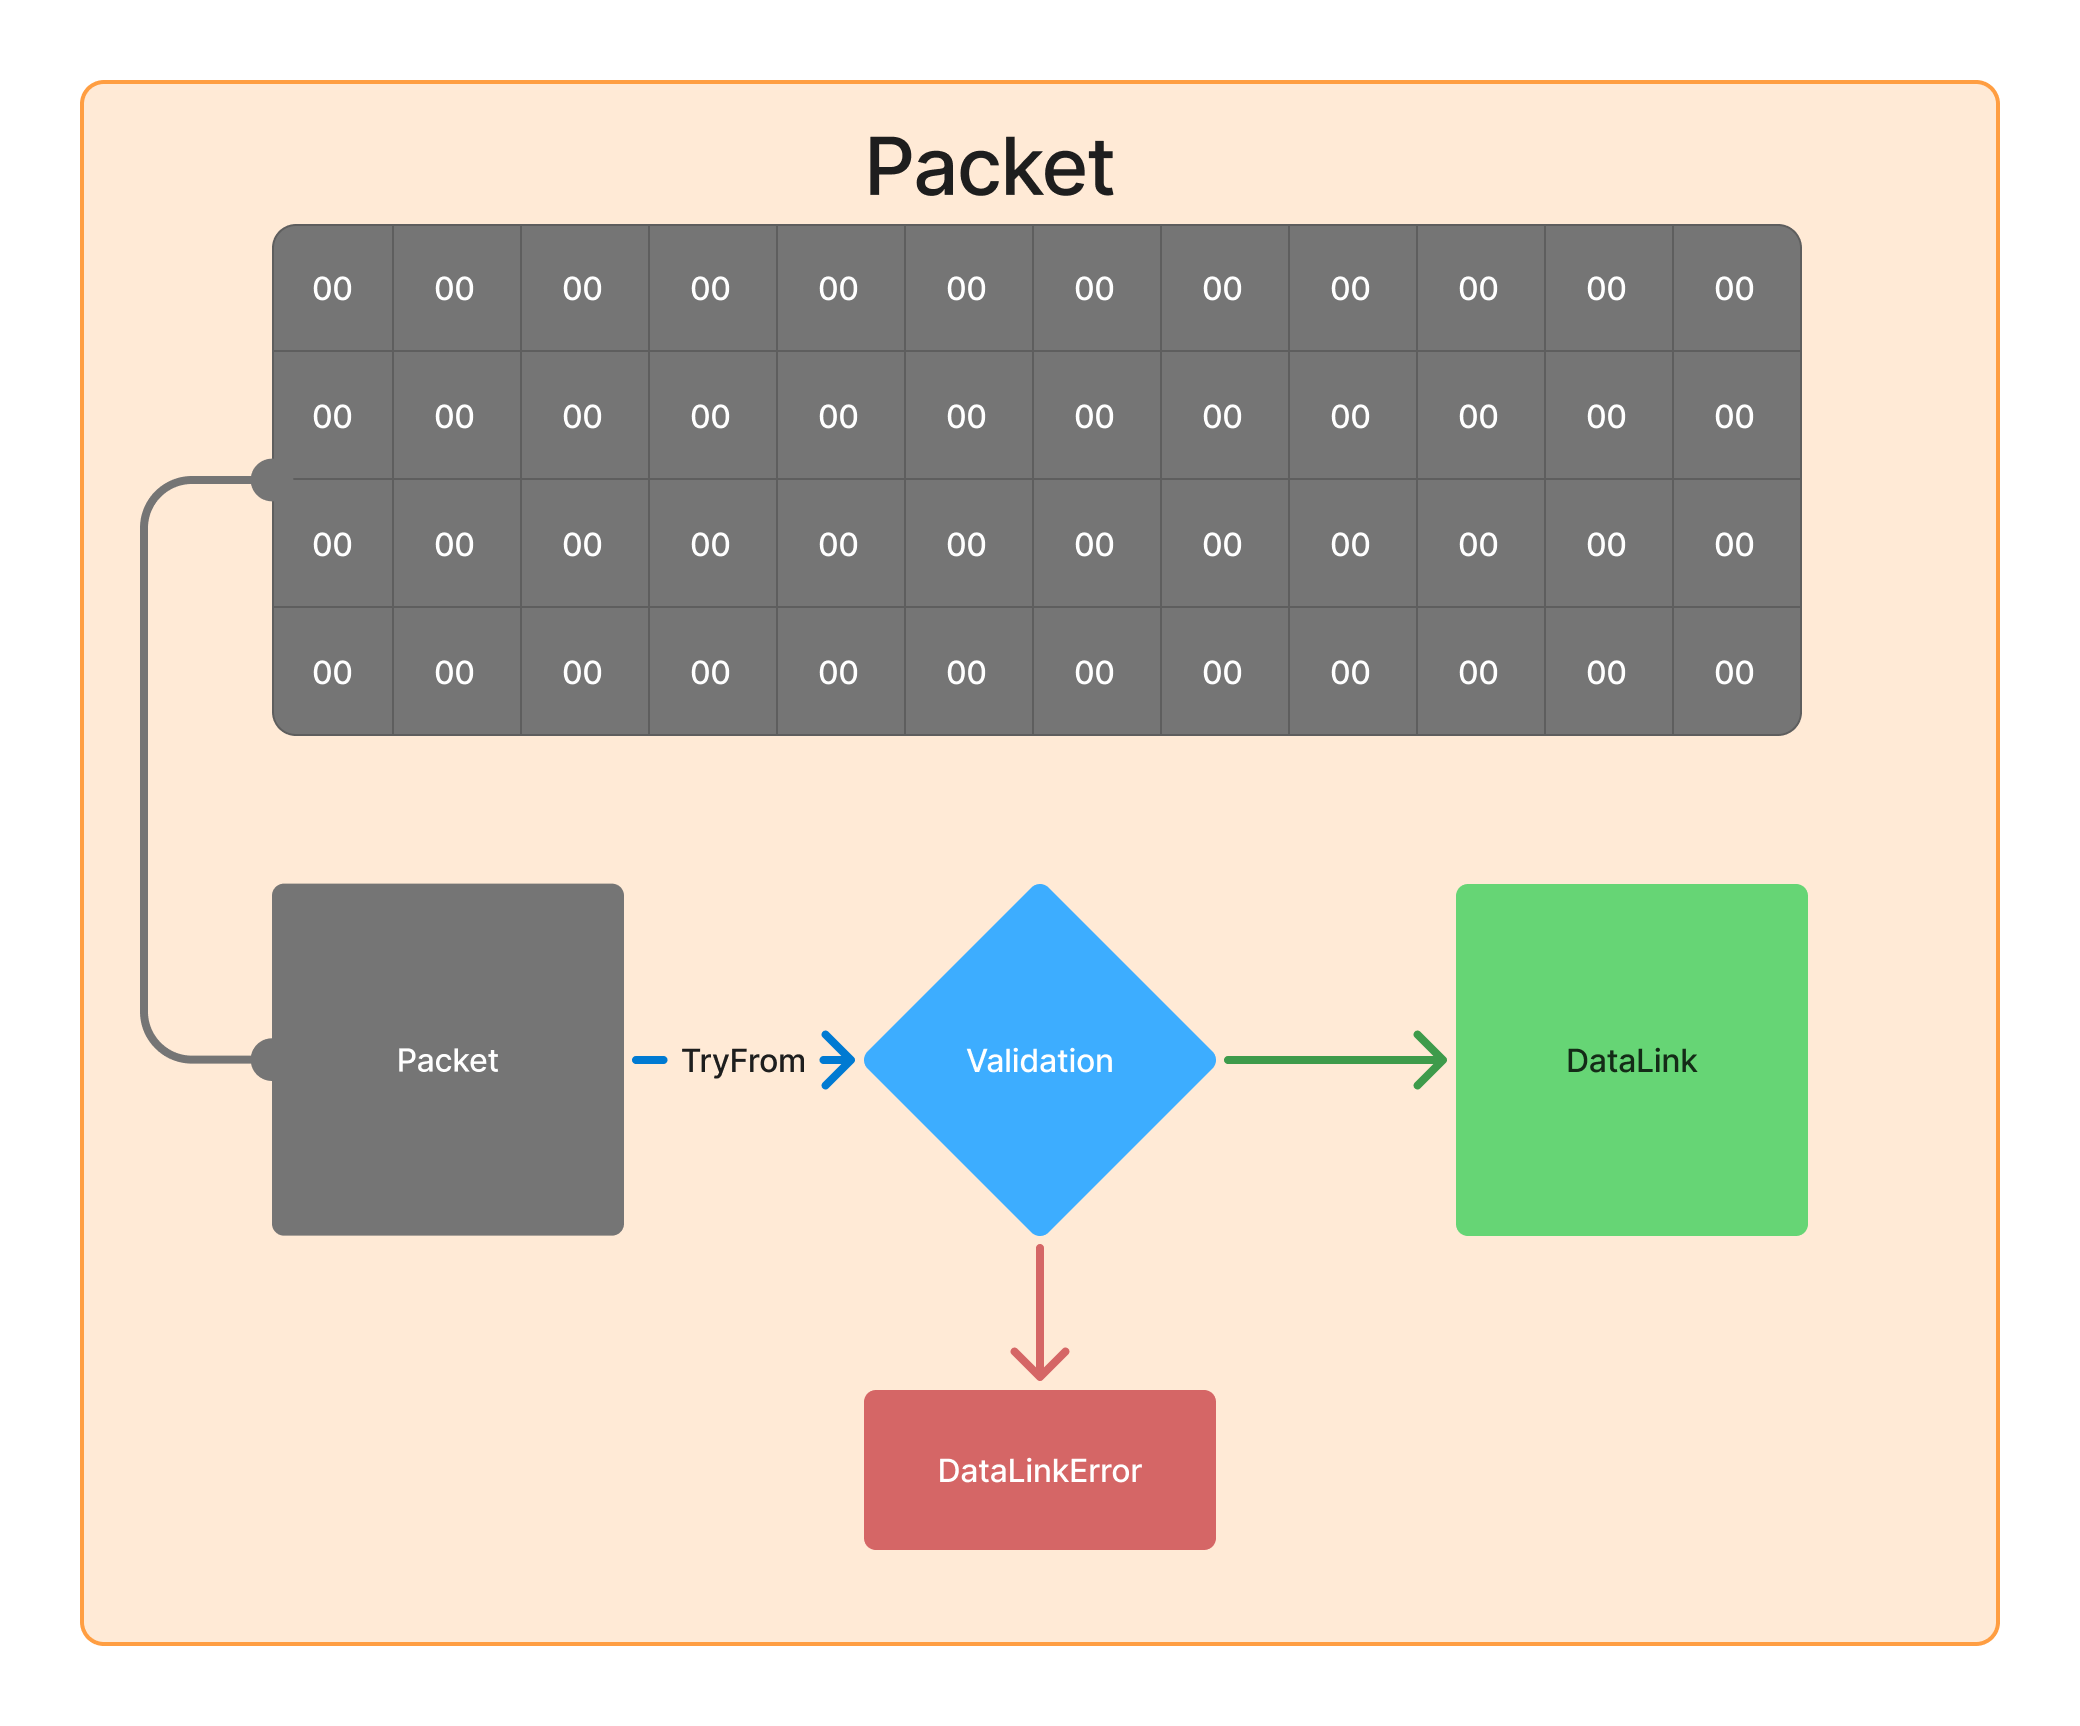
Validations
While parsing, I implemented validations to ensure the raw packet is coherent.
📌 Validations Performed:
✅ Frame minimum length – the packet is at least 14 bytes (MAC_DST + MAC_SRC + EtherType), otherwise DataLinkError::DataLinkTooShort { required, actual }.
✅ VLAN stack length – re-checked at each tag consumed: 14 + 4 × tags bytes, so a frame truncated in the middle of the stack reports DataLinkTooShort instead of an out-of-bounds access.
✅ MAC address length – exactly 6 bytes, MacParseError::InvalidLength otherwise (unreachable from DataLink::try_from, since the frame length is already proven; it protects the direct MacAddress::try_from).
The EtherType is not validated: an unknown value is a valid frame carrying a protocol we do not decode, and the internet layer will simply be None.
#![allow(unused)]
fn main() {
impl<'a> TryFrom<&'a [u8]> for DataLink<'a> {
    type Error = DataLinkError;

    fn try_from(packets: &'a [u8]) -> Result<Self, Self::Error> {
        validate_data_link_length(packets)?;

        let destination_mac = MacAddress::try_from(&packets[0..6])?;
        let source_mac = MacAddress::try_from(&packets[6..12])?;

        let raw_ethertype = u16::from_be_bytes([packets[12], packets[13]]);
        if VlanTag::is_tpid(raw_ethertype) {
            return Self::parse_tagged(packets, destination_mac, source_mac, raw_ethertype);
        }

        Ok(DataLink {
            destination_mac,
            source_mac,
            vlan: None,
            vlan_stack: VlanStack::default(),
            ethertype: Ethertype::from(raw_ethertype),
            payload: &packets[14..],
        })
    }
}
}
Structuring the Parsed Frame
After extracting all components, I structured the parsed frame in a clear format. This makes it easier to analyze, debug, and process packets dynamically.
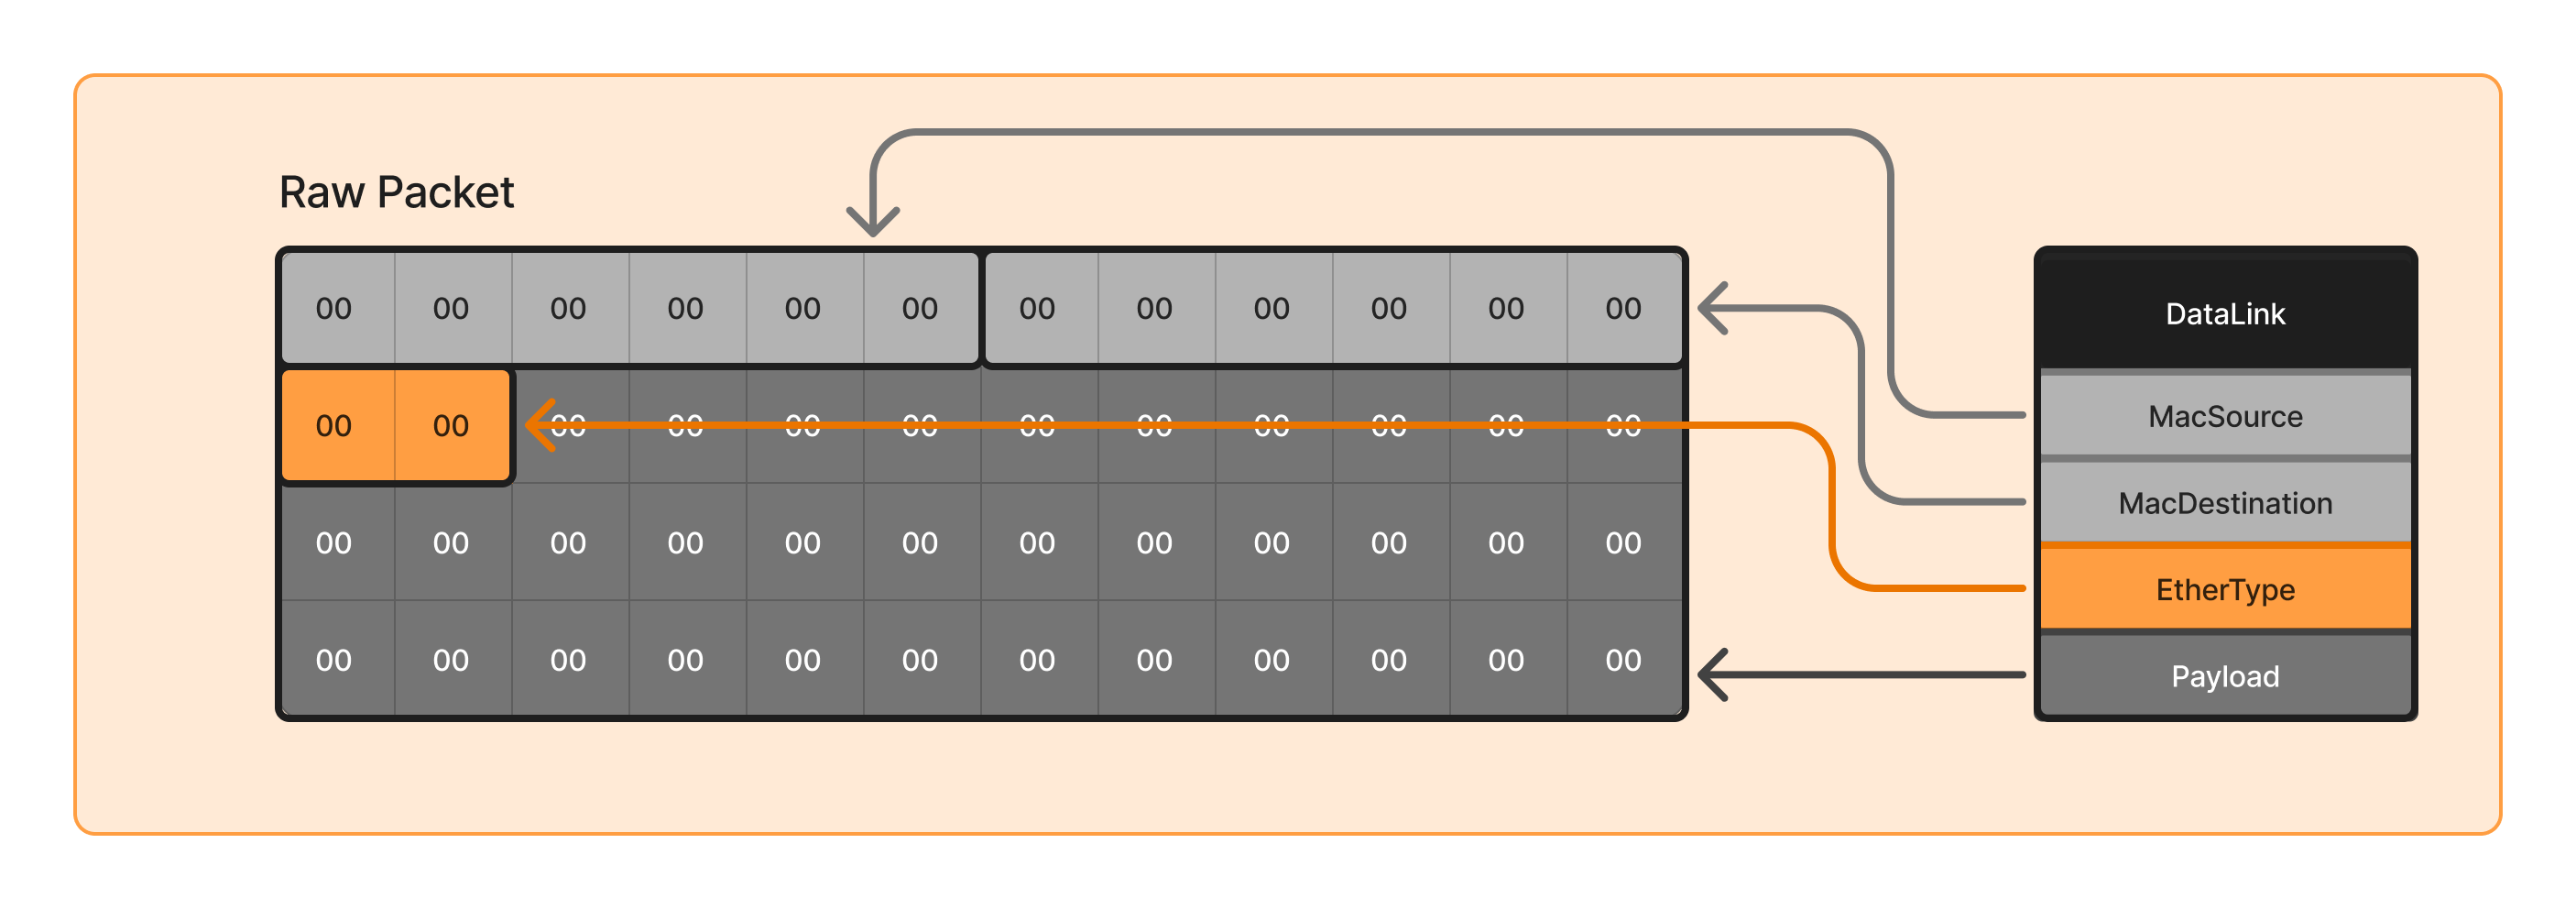
🌐 Beyond Ethernet: LinkType and LinkLayer
A capture is not always Ethernet. A capture on the Linux any interface is Linux cooked (SLL), a VPN capture is often RAW IP, an industrial capture can be 802.3br. The bytes of these formats look nothing like an Ethernet header, and nothing in them says which format they are: only the capture file knows, through its LINKTYPE.
That is why parse takes a LinkType and never guesses. LinkType(pub u32) uses the canonical LINKTYPE_* values stored in PCAP/PCAPNG files, and stays open: an unknown value is preserved, not collapsed into an Unknown variant.
#![allow(unused)]
fn main() {
const fn decoder_for(link_type: LinkType) -> Option<DecoderKind> {
    match link_type {
        LinkType::NULL => Some(DecoderKind::Null),
        LinkType::ETHERNET => Some(DecoderKind::Ethernet),
        // RAW, IPV4 and IPV6 share one decoder: bytes start at the IP header,
        // and the version nibble says which one.
        LinkType::RAW => Some(DecoderKind::RawIp(LinkType::RAW)),
        LinkType::IPV4 => Some(DecoderKind::RawIp(LinkType::IPV4)),
        LinkType::IPV6 => Some(DecoderKind::RawIp(LinkType::IPV6)),
        LinkType::LINUX_SLL => Some(DecoderKind::LinuxSll),
        LinkType::LINUX_SLL2 => Some(DecoderKind::LinuxSll2),
        LinkType::IEEE802_3BR => Some(DecoderKind::Ieee8023br),
        _ => None,
    }
}
}
This function is the single source of truth: is_supported is decoder_for(..).is_some(), and parse returns ParseError::UnsupportedLinkType before reading a single byte when it is None.
Every decoder produces the same format-neutral output, consumed by the shared L3/L4/L7 pipeline:
#![allow(unused)]
fn main() {
pub struct LinkLayer<'a> {
    link_type: LinkType,               // the LINKTYPE it was decoded as
    network_protocol: NetworkProtocol, // what comes next: Ipv4, Ipv6, Arp, Profinet, Other(u16)
    network_payload: &'a [u8],         // the L3 bytes
    kind: LinkLayerKind<'a>,           // the format-specific view
}

pub enum LinkLayerKind<'a> {
    Ethernet(DataLink<'a>),
    RawIp(RawIpLink<'a>),
    LinuxSll(LinuxSllLink<'a>),
    LinuxSll2(LinuxSll2Link<'a>),
    Ieee80211(Ieee80211Link<'a>),
}
}
NetworkProtocol is deliberately independent from Ethernet: RAW IP announces Ipv4 or Ipv6 without fabricating an EtherType, while Ethernet and SLL map their protocol field to the same value. The common accessors (link_type(), network_protocol(), network_payload()) never assume Ethernet; the format-specific views are explicit:
#![allow(unused)]
fn main() {
println!("LINKTYPE={}", flow.data_link.link_type());
println!("next={:?}", flow.data_link.network_protocol());

if let Some(ethernet) = flow.data_link.as_ethernet() {
    println!("{} -> {}", ethernet.source_mac, ethernet.destination_mac);
}
if let Some(sll) = flow.data_link.as_linux_sll() {
    println!("{} type={}", sll.hardware_type, sll.packet_type);
}
}
So a RAW or SLL capture cannot silently manufacture MAC addresses, which is what happened before this design when everything was forced through DataLink.
Per-format notes
- BSD loopback (NULL, LINKTYPE 0), since 11.2.0: four bytes of address family, then the IP packet. The family is written in the byte order of the capturing host and the format keeps no trace of it, so the field is read both ways and only a reading consistent with the IP version nibble is kept: it is a cross-check, not the source of truth. An unknown or contradicting family is
LinkLayerError::InvalidAddressFamily.LINKTYPE_LOOP(108), the OpenBSD twin in network order, is deliberately not handled: no capture attests it. - Linux SLL v1 (16-byte cooked header): keeps the packet type, the raw ARPHRD hardware type, the declared address length, the available source-address bytes and the protocol value. An address longer than the 8-byte wire slot is reported as truncated (
address_is_truncated()) rather than rejected. UseLinkType::LINUX_SLL(113): the value 25 shown by some Wireshark fields is an internal WTAP identifier. - Linux SLL v2 (20-byte header): additionally keeps the interface index and the reserved-MBZ field. A non-zero reserved value is preserved and reported by
reserved_is_zero(), matching Tshark's tolerant dissection. - RAW IP: an empty packet or a version nibble other than 4/6 is
LinkLayerError::InvalidIpVersion. WithLinkType::IPV4/IPV6the declared version is checked against the nibble. - IEEE 802.3br: express mPackets (SMD-E) are decoded as Ethernet after their preamble; preemptible fragments (SMD-S/C) are refused with
LinkLayerError::PreemptibleFragment, their reassembly being stateful. - IEEE 802.11: modelled (
Ieee80211Link) for the inner flows of a CAPWAP tunnel, not yet decodable as a top-level LINKTYPE.
One error path
Whatever the format, a link failure is reported through the same enum, with sizes expressed on the whole packet:
#![allow(unused)]
fn main() {
Err(ParseError::InvalidLinkLayer(LinkLayerError::Truncated {
    link_type, required, actual,
}))
}
STP lives here too
Spanning Tree BPDUs are 802.3 frames (a length field instead of an EtherType) sent to 01:80:c2:00:00:00 with an LLC header 42-42-03. They have no network layer. Without a dedicated check they came out with L3/L4/L7 all None and no signal, so the pipeline validates the BPDU and labels the flow application_protocol: "STP" directly from the link layer.
🚀 Conclusion
Parsing the Data Link Layer requires careful validation and structured extraction. By following a modular approach:
- MAC addresses are extracted safely.
- EtherType is correctly mapped, VLAN stacks are consumed.
- The LINKTYPE is trusted, the bytes are not: each format has its own decoder, and none of them can be mistaken for another.
- The structure is extensible to new link formats without touching the L3/L4/L7 pipeline.
🚀 Next Step: exploring the internet layer (IPv4/IPv6/ARP)!
Internet
The internet layer is the first optional layer: it is parsed from LinkLayer::network_payload(), and the link layer says which protocol to expect through NetworkProtocol.
The Internet struct
#![allow(unused)]
fn main() {
pub struct Internet<'a> {
    pub source: Option<IpAddr>,
    pub source_type: Option<IpType>,
    pub destination: Option<IpAddr>,
    pub destination_type: Option<IpType>,
    /// "IPv4", "IPv6", "ARP", "Profinet"
    pub protocol_name: &'static str,
    /// Transport protocol parsable from `payload`. `None` for IPv4 fragments.
    pub payload_protocol: Option<TransportProtocol>,
    pub payload: &'a [u8],
    /// Full parsed header: Ipv4Packet, Ipv6Packet or ArpPacket.
    pub details: Option<InternetDetails<'a>>,
}
}
Addresses use the standard std::net::IpAddr, and each one is classified by IpType: Private, Public, Loopback, LinkLocal, Apipa, Ula, Multicast, Broadcast (limited broadcast 255.255.255.255), Documentation, Unknown. This is what lets a consumer filter "traffic to the Internet" without re-implementing RFC 1918.
Dispatch on the announced protocol, not probing
The link layer already told us what the payload is. The internet parser trusts that announcement:
#![allow(unused)]
fn main() {
pub fn try_from_network_parts(protocol: NetworkProtocol, payload: &'a [u8])
    -> Result<Self, InternetError>
{
    match protocol {
        NetworkProtocol::Arp => Ok(Self::from_arp(ArpPacket::try_from(payload)?)),
        NetworkProtocol::Ipv4 => Ok(Self::from_ipv4(Ipv4Packet::try_from(payload)?)),
        NetworkProtocol::Ipv6 => Ok(Self::from_ipv6(Ipv6Packet::try_from(payload)?)),
        NetworkProtocol::Profinet => { ProfinetPacket::try_from(payload)?; Ok(Self::profinet()) }
        NetworkProtocol::Other(_) => Err(InternetError::UnsupportedProtocol),
    }
}
}
Why dispatch rather than "try ARP, then IPv4, then IPv6"? Because probing cannot tell a corrupt packet from an unknown protocol: both just fail every parser. With the EtherType in hand, the two cases are distinct, and the pipeline maps them to the two distinct outcomes:
#![allow(unused)]
fn main() {
match Internet::try_from_network_parts(network_protocol, network_payload) {
    Ok(internet) => (Some(internet), None),
    Err(InternetError::UnsupportedProtocol) => (None, None),   // e.g. LLDP: not our job
    Err(e) => (None, Some(CorruptedLayer {                     // said IPv4, was garbage
        layer: CorruptedLayerKind::Internet,
        error: e.to_string(),
    })),
}
}
Internet::try_from(&[u8]) (the probing version) still exists for callers that only have raw L3 bytes, but PacketFlow never uses it.
IPv4 validations
packet-beta
0-3: "Version"
4-7: "IHL"
8-15: "DSCP/ECN"
16-31: "Total length"
32-47: "Identification"
48-50: "Flags"
51-63: "Fragment offset"
64-71: "TTL"
72-79: "Protocol"
80-95: "Header checksum"
96-127: "Source address"
128-159: "Destination address"
160-191: "Options (if IHL > 5)"
✅ Minimum length – at least 20 bytes.
✅ Version – the high nibble is 4.
✅ Header length – IHL × 4 is between 20 and 60 bytes (IHL 5..=15).
✅ Header available – the buffer holds the whole header, options included.
✅ Total length – total_length is at least the header length and at most the buffer length. The payload is data[header_len..total_length]: Ethernet padding after a short IP packet is not handed to the transport layer.
The header checksum is not verified here: on a sender-side capture with hardware offloading it is often uncomputed, and a mandatory check would reject perfectly healthy traffic. packet_parser::checksum::verify_ipv4_header_checksum is available when the context allows it.
Fragments
The crate does no IP reassembly. For a fragmented IPv4 packet (MF flag set or non-zero offset), payload_protocol is set to None so the transport layer is not parsed from incomplete data: a TCP header read from the second fragment of a datagram would be garbage with valid-looking ports. Ipv4Packet::is_fragmented() and is_non_initial_fragment() expose the flags through details.
IPv6 validations
✅ Header length – at least 40 bytes.
✅ Version – the high nibble is 6.
✅ Payload length – the buffer holds 40 + payload_length bytes.
Extension headers are walked to find the real transport protocol: Ipv6Packet::transport_protocol is the next header after the extension chain, and extension_headers keeps the raw bytes of the chain. As for IPv4, a Fragment extension header (or a No Next Header value) sets transport_protocol to None, so nothing is parsed above an incomplete datagram.
ARP
ARP carries no transport, but it does carry protocol addresses, and those are worth a flow identity: source/destination are the sender/target protocol addresses, payload_protocol is None, and details holds the full ArpPacket (hardware/protocol types and lengths, operation, both hardware addresses).
✅ Minimum length 28 bytes, hardware type 1 (Ethernet) with length 6, protocol type IPv4 (length 4) or IPv6 (length 16), operation request/reply, and the dynamic length 8 + 2×hlen + 2×plen available.
Profinet
Profinet (EtherType 0x8892) is validated so that a corrupt frame is reported, but the crate keeps no detailed header for it: Internet::profinet() has no addresses and no payload.
IP-level tunnels
GRE (protocol 47) and IP-in-IP (protocols 4 and 41) are detected from payload_protocol at this level, before any transport parsing, because they have no transport layer. See the tunnels chapter.
Transport
The transport layer is parsed from Internet::payload, and the internet layer says what to expect through payload_protocol.
The Transport struct
#![allow(unused)]
fn main() {
pub struct Transport<'a> {
    pub protocol: TransportProtocol,
    pub source_port: Option<u16>,
    pub destination_port: Option<u16>,
    /// The bytes handed to the application layer. `None` when nothing stacks above.
    pub payload: Option<&'a [u8]>,
    /// Full parsed header: TcpPacket, UdpPacket, IcmpPacket or Icmpv6Packet.
    pub details: Option<TransportDetails<'a>>,
}
}
TransportProtocol maps every IANA protocol number (Tcp, Udp, Icmp, Ipv6Icmp, Gre, Sctp, Ospf...), so a packet carrying a protocol without a dedicated parser still gets a correct protocol label. Only TCP, UDP, ICMPv4 and ICMPv6 are decoded further.
Dispatch on the IP protocol number
#![allow(unused)]
fn main() {
pub fn try_from_parts(payload_protocol: Option<TransportProtocol>, payload: &'a [u8])
    -> Result<Self, TransportError>
{
    match payload_protocol {
        Some(TransportProtocol::Tcp) => { let tcp = TcpPacket::try_from(payload)?; /* ports, payload, details */ }
        Some(TransportProtocol::Udp) => { let udp = UdpPacket::try_from(payload)?; /* ... */ }
        Some(TransportProtocol::Icmp) => Ok(Transport { /* no ports, payload: None, details: IcmpPacket::try_from(payload).ok() */ }),
        Some(TransportProtocol::Ipv6Icmp) => Ok(Transport { /* same with Icmpv6Packet */ }),
        Some(other) => Ok(Transport { protocol: other, source_port: None, destination_port: None, payload: None, details: None }),
        None => Err(TransportError::UnsupportedProtocol),
    }
}
}
Same philosophy as the internet layer: the protocol number decides, there is no probing, and UnsupportedProtocol (which PacketFlow maps to transport: None, corrupted: None) is distinct from a TCP or UDP parse error (corrupted: Transport).
TCP validations
packet-beta
0-15: "Source port"
16-31: "Destination port"
32-63: "Sequence number"
64-95: "Acknowledgment number"
96-99: "Data offset"
100-102: "Reserved"
103-111: "Flags (NS CWR ECE URG ACK PSH RST SYN FIN)"
112-127: "Window size"
128-143: "Checksum"
144-159: "Urgent pointer"
160-191: "Options (if data offset > 5)"
Structural checks (an Err means "not a readable TCP header"):
✅ Minimum length – at least 20 bytes.
✅ Data offset – between 5 and 15 words (20 to 60 bytes).
✅ Header available – the buffer holds the whole header, options included.
Semantic checks (the header is readable, TryFrom returns Ok, and the anomaly is exposed by TcpPacket::anomaly()):
⚠️ SYN + FIN both set – no conforming stack opens and closes a connection in the same segment. This is a classic scan and firewall-evasion signature (TcpError::InvalidFlags).
⚠️ Reserved bits set – RFC 9293 says they must be zero (TcpError::ReservedBitsSet).
The pipeline keeps an anomalous transport, with its ports, and reports it in corrupted. Its payload is not handed to the application probes: bytes that did not come from a conforming stack are not worth classifying.
#![allow(unused)]
fn main() {
if let Some(corrupted) = &flow.corrupted
    && corrupted.layer == CorruptedLayerKind::Transport
{
    match &flow.transport {
        None => { /* structural: unreadable header */ }
        Some(transport) => { /* semantic: ports usable, packet suspicious */ }
    }
}
}
UDP validations
✅ Minimum length – at least 8 bytes.
✅ Length field – equal to the buffer length. UDP is the one header whose declared length must match exactly: the internet layer already trimmed the Ethernet padding, so a mismatch is a corrupt datagram.
ICMPv4 and ICMPv6
ICMP has neither ports nor sessions. It is reached through the IP protocol number (1, or next header 58 for ICMPv6), never through probing, and the two versions have separate parsers: their type numbering is disjoint (128 is an echo request in ICMPv6, 8 is undefined there).
Two deliberate choices:
payloadstaysNone: nothing stacks above ICMP, and exposing its bytes would hand them to the application probes, which would mislabel them. The decoded message is indetails(TransportDetails::Icmp/Icmpv6).- an unreadable ICMP message does not corrupt the flow: the protocol is correctly identified by the IP header, so
protocolis set and onlydetailsfalls back toNone.
Decoded messages: echo request/reply, the error reports that quote the original datagram (destination unreachable, redirect, time exceeded, parameter problem), and for ICMPv6 the neighbor discovery messages of RFC 4861 (router/neighbor solicitation and advertisement with their flags, lifetimes and target address).
Checksums
TCP and UDP checksums are never verified during parsing, for the same offloading reason as IPv4. They need the IP pseudo-header, so the opt-in functions take the addresses:
#![allow(unused)]
fn main() {
use packet_parser::checksum::verify_tcp_checksum;

// Some(true): present and correct; Some(false): present and wrong;
// None: not verifiable (too short, or UDP checksum absent).
let ok = verify_tcp_checksum(internet.source?, internet.destination?, internet.payload);
}
Application
The application layer is where the rule "the port never decides alone" is put to the test, and where most of the design decisions of the crate were taken after real captures proved a naive approach wrong.
A classification, not a decode
#![allow(unused)]
fn main() {
pub struct Application {
    pub application_protocol: &'static str,   // "DNS", "TLS", "HTTP", "Unknown"...
}
}
PacketFlow::application is a label. It says which protocol the transport payload looks like, not what the message contains. It is &'static str, so classification costs no allocation.
For the actual decode, every protocol has a module under packet_parser::parse::application::protocols, and every one of them is a TryFrom<&[u8]> with its own struct and error:
#![allow(unused)]
fn main() {
use packet_parser::parse::application::protocols::dns::DnsPacket;

if let Some(transport) = &flow.transport
    && let Some(payload) = transport.payload
    && let Ok(dns) = DnsPacket::try_from(payload)
{
    println!("{} questions, {} answers", dns.header.qdcount, dns.header.ancount);
}
}
Why separate the two? Because the label is the thing every consumer needs on every packet (a flow matrix, a protocol histogram), and it must be cheap and stateless. Decoding DNS names or TLS extensions allocates and only some consumers need it.
Supported protocols
DNS (plus mDNS and LLMNR forms), TLS, SNMP, NTP, DHCP, DHCPv6, HTTP, MQTT, PostgreSQL, FTP, SMTP, NNTP, SSH (identification string only), SSDP, NetBIOS (NBNS, NBSS), OpenVPN, Modbus TCP, UMAS, EtherNet/IP, OPC UA, S7Comm, COTP, AMS, GIOP, SRVLOC, QUIC, Bitcoin, and STP from the link layer.
A probed payload that matches nothing is labelled "Unknown". An empty payload (a pure ACK) is not probed at all and application stays None.
How the label is chosen: one ordered table
The first version of the crate was a cascade of if XxxPacket::try_from(payload).is_ok() { return "Xxx" }, spread over two files, with port guards applied unevenly and one override where the port beat the content. Three problems showed up on real traffic:
- false positives: NTP probed on TCP labelled TLS encrypted alerts "NTP" (
0x15is a plausible LI/VN/mode byte); a BOOTP packet looked like an SLP header; FTP/SMTP/NNTP replies are byte-for-byte identical; - double probing: the same parser ran twice on the same payload (once port-guarded, once blind);
- pathological cost: a 64 KiB GRO segment was fully parsed by every probe in the cascade.
The dispatch is now one ordered table in src/parse/dispatch.rs. Each rule has:
#![allow(unused)]
fn main() {
struct Rule {
    label: &'static str,
    guard: Guard,                              // Tcp, Udp or Any: the transports the RFC allows
    ports: Option<fn(Option<u16>) -> bool>,    // optional port guard (either port)
    ports_veto: Option<fn(Option<u16>) -> bool>, // ports on which the rule must NOT fire
    probe: ProbeId,                            // the content check
    terminal_on_port: bool,                    // port reserved by RFC: the verdict is final
}
}
and the invariants are:
- A rule with a port guard labels only if port and content agree. The port alone never decides.
OPC UAon port 4840 is still checked byOpcuaPacket::try_from. - Every probe runs at most once per payload. Failures are memoized by
ProbeIdin a bitmask: a rule sharing a probe with an earlier one (port-priority then blind fallback) never re-runs it. - Probes read at most
PROBE_CAP= 18 KiB. Classification is a verdict on the application header, not on the whole segment; the cap is above the largest legitimate message a probe must see in full (an encrypted TLS record: 5 + 16 KiB + tag). The one exception is OpenVPN over TCP, whose length prefix is checked against the real payload. - The order of the table is the priority, inspectable, testable, and locked by a golden snapshot over the reference captures.
Reading the table
#![allow(unused)]
fn main() {
static RULES: &[Rule] = &[
    // --- port-guarded rules: weak signature confirmed by the port ---
    port_rule("SNMP",   Guard::Udp, is_snmp_udp_port,   ProbeId::Snmp),     // 161, 162
    port_rule("DHCPv6", Guard::Udp, is_dhcpv6_udp_port, ProbeId::Dhcpv6),   // 546, 547
    rule("S7Comm", Guard::Tcp, ProbeId::S7Comm),   // strong enough for blind TCP probing, before COTP
    port_rule("COTP",   Guard::Tcp, is_iso_tsap_tcp_port, ProbeId::CotpTpkt), // 102
    port_rule("FTP",    Guard::Tcp, is_ftp_tcp_port,  ProbeId::Ftp),        // 21
    port_rule("SMTP",   Guard::Tcp, is_smtp_tcp_port, ProbeId::Smtp),       // 25, 587
    port_rule("NNTP",   Guard::Tcp, is_nntp_tcp_port, ProbeId::Nntp),       // 119
    // FTP/SMTP/NNTP off-port: only verbs that exist in exactly one of the three
    // (RETR, STOR, EHLO, MAIL, ARTICLE, XOVER...), vetoed on the three standard ports
    // where such a verb is probably content in transit (a DATA body, an article).
    Rule { label: "FTP", ports_veto: Some(is_text_protocol_port), probe: ProbeId::FtpUnambiguous, .. },
    // mDNS 5353 and LLMNR 5355 are reserved by their RFCs: terminal ports.
    Rule { label: "mDNS", ports: Some(is_mdns_udp_port), terminal_on_port: true, .. },
    port_rule("SSDP",    Guard::Udp, is_ssdp_udp_port, ProbeId::Ssdp),      // 1900
    port_rule("NBNS",    Guard::Udp, is_nbns_udp_port, ProbeId::Nbns),      // 137
    port_rule("NBSS",    Guard::Tcp, is_nbss_tcp_port, ProbeId::Nbss),      // 139, 445
    port_rule("OpenVPN", Guard::Udp, is_openvpn_port,  ProbeId::OpenVpnUdp),// 1194
    port_rule("AMS",     Guard::Tcp, is_ams_tcp_port,  ProbeId::Ams),       // 48898
    port_rule("QUIC",    Guard::Udp, is_quic_udp_port, ProbeId::QuicShortHeader), // 443: 1-RTT header is opaque
    port_rule("OPC UA",  Guard::Tcp, is_opcua_tcp_port, ProbeId::Opcua),    // 4840: priority, not sufficiency
    port_rule("DNS",     Guard::Tcp, is_dns_port, ProbeId::DnsTcp),         // 53: length-prefixed form
    port_rule("DNS",     Guard::Udp, is_dns_port, ProbeId::Dns),            // 53: datagram form
    // --- blind cascade, with the transport guards the RFCs impose ---
    rule("NTP",         Guard::Udp, ProbeId::Ntp),
    rule("Bitcoin",     Guard::Tcp, ProbeId::Bitcoin),
    rule("OPC UA",      Guard::Tcp, ProbeId::Opcua),       // memoized: not re-run if the port rule failed
    rule("EtherNet/IP", Guard::Any, ProbeId::EthernetIp),  // truly bi-transport (TCP 44818, UDP 2222)
    rule("PostgreSQL",  Guard::Tcp, ProbeId::Postgresql),
    rule("DNS",         Guard::Udp, ProbeId::Dns),         // datagram form exists only on UDP
    rule("SNMP",        Guard::Any, ProbeId::Snmp),        // SNMP over TCP exists (RFC 3430)
    rule("TLS",         Guard::Tcp, ProbeId::Tls),
    rule("SSH",         Guard::Tcp, ProbeId::Ssh),         // literal "SSH-" prefix, before HTTP
    rule("HTTP",        Guard::Tcp, ProbeId::Http),
    rule("GIOP",        Guard::Tcp, ProbeId::Giop),
    rule("DHCP",        Guard::Udp, ProbeId::Dhcp),        // before SRVLOC: a BOOTP mimicked an SLP header
    rule("SRVLOC",      Guard::Any, ProbeId::Srvloc),
    rule("UMAS",        Guard::Tcp, ProbeId::Umas),
    rule("ModbusTCP",   Guard::Tcp, ProbeId::ModbusTcp),
    rule("QUIC",        Guard::Udp, ProbeId::QuicLongHeader),
    rule("MQTT",        Guard::Tcp, ProbeId::Mqtt),        // last: its fixed header is barely discriminating
];
}
Each comment in the real file cites the capture frame or the issue that motivated the line. That is the point of a table over a cascade: the semantics of the order are written down and cannot silently move.
Three detection routes
When choosing where a new protocol goes, the question is: can a valid payload of this protocol also be a valid payload of another protocol we already detect, or of arbitrary text?
| Route | When | Example |
|---|---|---|
Blind probe (rule) | the bytes identify themselves: literal marker (HTTP/, GIOP, SSH-), tight binary header (DNS, NTP), announced length that must match exactly (PostgreSQL) | rule("TLS", Guard::Tcp, ..) |
Port-guarded (port_rule) | the signature is weak or ambiguous even with perfect checks: identical reply syntax (FTP/SMTP/NNTP), loose headers (DHCPv6, AMS, COTP, QUIC short header), relaxed validation (mDNS) | port_rule("FTP", Guard::Tcp, is_ftp_tcp_port, ..) |
| Strong signature with transport constraint | recognizable off-port, but only defined on one transport | S7Comm: the full TPKT + COTP-DT + S7 envelope is probed on any TCP port, and the same bytes on UDP never yield the label |
Whatever the route, the transport guard is always there: the RFC says on which transport a protocol exists, and probing it elsewhere only produces false positives.
"Decode As"
Port guards mean a server on a non-standard port is invisible to a port-guarded rule. ParseConfig::decode_as(port, DecodeAsProtocol::Xxx) declares extra ports. Declared ports are evaluated before the table, with the same three constraints: port and content, the protocol's transport guard, and failures memoized like the table's. Ports the table marks terminal (mDNS 5353, LLMNR 5355) cannot be overridden: the caller extends the guards, never replaces them.
STP: the one label without a transport
A Spanning Tree BPDU has no L3, so it can never reach this table. The pipeline checks it from the link layer (802.3 length field, bridge group address, LLC 42-42-03, valid BPDU) and labels the flow "STP" when every other layer is None.
Tunnels take the label
When the transport payload is a recognized encapsulation (CAPWAP, VXLAN, Geneve, GTP-U) the outer flow's application_protocol is the tunnel name, and the real conversation is in inner. Next chapter.
Tunnels
Some packets carry a whole other packet inside their payload. The base pipeline is layered and single-level: without help it only sees the outer flow (say, UDP between two data centres) and misses the real conversation nested inside.
inner and flatten()
When a tunnel is recognized, its name goes into the outer flow's application_protocol, its headers are peeled, and the encapsulated packet is fed back into the same L3/L4/L7 pipeline, recursively, into inner:
#![allow(unused)]
fn main() {
pub struct PacketFlow<'a> {
    // ...
    pub inner: Option<Box<PacketFlow<'a>>>,
}
}
One wire packet then yields several flow levels, outermost first:
#![allow(unused)]
fn main() {
let flow = parse(LinkType::ETHERNET, &packet)?;

for level in flow.flatten() {
    println!("{:?} -> {:?}", level.internet, level.transport);
}
}
A non-tunneled packet yields one entry. The inner flows borrow the same buffer as the outer one: peeling is zero-copy, only the recursion boxes.
Nesting is bounded by MAX_TUNNEL_DEPTH = 4, an anti-loop guard against malformed traffic that could claim endless encapsulation.
Supported tunnels
| Tunnel | Detected from | Inner |
|---|---|---|
| CAPWAP-Data (RFC 5415) | UDP/5247 | IEEE 802.11 → LLC/SNAP → L3 |
| GRE v0 (RFC 2784/2890) | IP protocol 47 | IPv4, IPv6 or Ethernet (0x6558) |
| IP-in-IP | IP protocols 4 and 41 | bare IPv4 / IPv6 |
| VXLAN (RFC 7348) | UDP/4789 | full Ethernet frame |
| Geneve (RFC 8926) | UDP/6081 | Ethernet (0x6558) or bare IP, options skipped |
| GTP-U (3GPP TS 29.281) | UDP/2152 | bare IP, no L2 |
Two detection points
Tunnels are looked for at two places in the pipeline, because they live at two levels:
- IP-level (
detect_inner_l3), fromInternet::payload_protocol, before transport parsing: GRE and IP-in-IP have no transport layer, so their detection cannot depend on the hollowTransportthe catch-all branch oftry_from_partsbuilds for them. For IP-in-IP, the outer protocol number announces the inner version (4 or 41), and the raw-IP decoder checks it against the inner version nibble: a mismatch is refused. - Transport-level (
detect_inner), from a UDP port and the payload shape: CAPWAP, VXLAN, Geneve, GTP-U.
Detection returns None, never an error: no tunnel, an encrypted payload (CAPWAP over DTLS), a truncated one, or a shape we don't decode all mean "this is just an ordinary flow".
Refuse, don't guess
Every tunnel decoder rejects the variants it cannot attest instead of guessing a shape: GRE version 1 (PPTP), ERSPAN and routing bits; VXLAN GBP/GPE flag extensions; Geneve OAM control messages; GTPv0, GTP' (a billing protocol on the same port) and every GTP-U message type other than G-PDU (echo requests and the whole control plane carry no user packet).
GTP-U is special in one way: alone among these, its header says nothing about what it carries (VXLAN is always Ethernet, Geneve announces an EtherType). So it is the only tunnel whose label requires the inner packet to parse cleanly first.
A fragmented outer datagram is never peeled: reassembly is stateful, and a tunnel must not be reported as more complete than the datagram carrying it.
The inner link layer is honest
The inner packet enters the pipeline through the same DecodedLink as a top-level packet: VXLAN produces an Ethernet link layer, GRE/Geneve/GTP-U produce a RawIp one, and CAPWAP produces an Ieee80211Link with the real 802.11 addresses and the SNAP protocol. Nothing fabricates an Ethernet header for a tunnel that does not carry one, which is the same principle as the data link chapter.
The "Decode As" configuration is propagated into the inner flows, so a declared port works inside a tunnel too.
Focus: GIOP
GIOP (General Inter-ORB Protocol) is the wire protocol of CORBA. It is the most complete application decoder of the crate, and the one whose development taught the most about parsing real traffic: two bugs were only found when the parser met genuine captures, and the final shape of the decoder — accept truncated messages, walk consecutive messages in a segment, resynchronize in the middle of a stream — comes straight from what an ORB actually puts on the wire. This chapter walks through it as a worked example of the method described in the previous chapters.
Module: packet_parser::parse::application::protocols::giop. Specification: CORBA formal/04-03-12, chapter 15. Supported: GIOP 1.0, 1.1 and 1.2, the eight message types, both endiannesses.
The message
packet-beta
0-31:   "Magic 'GIOP' (4 bytes)"
32-39:  "Major version u8 (1)"
40-47:  "Minor version u8 (0, 1, 2)"
48-55:  "Flags u8: bit 0 endianness, bit 1 more fragments (1.1+)"
56-63:  "Message type u8 (0..7)"
64-95:  "Message size u32 (body only, in the message's endianness)"
96-..:  "Body (CDR-encoded, layout depends on type and version)"
#![allow(unused)]
fn main() {
pub struct GiopPacket<'a> {
    pub header: GiopHeader,
    pub payload: GiopMessage<'a>,
    /// The buffer does not hold the whole body announced by `message_length`.
    pub truncated: bool,
    // bytes of the buffer covered by this message, header included
}

pub enum GiopMessage<'a> {
    Request(GiopRequest<'a>),
    Reply(GiopReply<'a>),
    CancelRequest(GiopCancelRequest),
    LocateRequest(GiopLocateRequest<'a>),
    LocateReply(GiopLocateReply<'a>),
    CloseConnection,        // header only
    MessageError,           // header only
    Fragment(GiopFragment<'a>),
    /// Valid type, unreadable body: the header stays reliable.
    Other,
}
}
Reading it
#![allow(unused)]
fn main() {
use packet_parser::parse::application::protocols::giop::{GiopMessage, GiopPacket, TargetAddress};

let packet = GiopPacket::try_from(tcp_payload)?;
let h = &packet.header;
println!("GIOP 1.{} {:?} little_endian={} size={} truncated={}",
    h.minor_version, h.message_type, h.is_little_endian(), h.message_length, packet.truncated);

if let GiopMessage::Request(request) = &packet.payload {
    println!("Request id={} op={} contexts={} stub={} bytes",
        request.request_id, request.operation,
        request.service_contexts.len(), request.stub_data.len());
    if let TargetAddress::KeyAddr(key) = &request.target {
        println!("target object key: {} bytes", key.len());
    }
}
}
On frame 4 of pcaps_exemple/protocols/giop/corba.pcap (the nDPI test corpus), this prints:
GIOP 1.2 Request little_endian=false size=216 truncated=false
Request id=0 op=echo contexts=1 stub=76 bytes
target object key: 60 bytes
and flow.application is labelled "GIOP" by the pipeline, through a blind TCP probe: the literal magic, a version in 1.0..1.2 and a known message type make a strong enough signature.
The book's example crate checks every one of these values on that frame — this is the test that pins down the difference between the pipeline's classification and the protocol parser's decode (tested):
#![allow(unused)]
fn main() {
    #[test]
    fn classification_is_a_label_the_protocol_parser_is_the_decode() {
        let raw = hex::decode(ETHERNET_IPV4_TCP_GIOP_REQUEST_HEX).unwrap();
        let flow = parse(LinkType::ETHERNET, &raw).unwrap();

        // The pipeline classifies the transport payload: a label, no decode.
        assert_eq!(flow.application.as_ref().unwrap().application_protocol, "GIOP");

        // The detailed parser decodes the same bytes.
        let payload = flow.transport.as_ref().unwrap().payload.unwrap();
        let packet = GiopPacket::try_from(payload).unwrap();
        assert_eq!(packet.header.minor_version, 2);
        assert_eq!(packet.header.message_type, GiopMessageType::Request);
        assert!(!packet.header.is_little_endian());
        assert_eq!(packet.header.message_length, 216);
        assert!(!packet.truncated);

        let GiopMessage::Request(request) = &packet.payload else {
            panic!("expected a Request, got {:?}", packet.payload);
        };
        assert_eq!(request.request_id, 0);
        assert_eq!(request.operation, "echo");
        assert_eq!(request.service_contexts.len(), 1);
        assert_eq!(request.stub_data.len(), 76);
        let TargetAddress::KeyAddr(key) = &request.target else {
            panic!("expected a KeyAddr target");
        };
        assert_eq!(key.len(), 60);
    }
}
The header: a TryFrom like the others
#![allow(unused)]
fn main() {
impl TryFrom<&[u8]> for GiopHeader {
    type Error = GiopParseError;

    fn try_from(payload: &[u8]) -> Result<Self, Self::Error> {
        ensure_min_len(payload)?;                                   // 12 bytes
        let magic = parse_magic(payload)?;                          // "GIOP"
        let (major_version, minor_version) = extract_version(&payload[4..6])?; // 1.0..1.2
        let flags = extract_flags(&payload[6])?;
        let message_type = GiopMessageType::try_from(payload[7])?;  // 0..7
        validate_message_type_in_version(payload[7], minor_version)?; // Fragment needs 1.1+
        let message_length = extract_message_size(&payload[8..12], flags & 0x01 != 0)?;
        Ok(GiopHeader { magic, major_version, minor_version, flags, message_type, message_length })
    }
}
}
Two details in this sequence are lessons from real frames:
message_sizefollows the endianness announced by the flags. The first version of the parser read it big-endian unconditionally. Frame 19 ofcorba.pcap, a little-endian Request carried inside a MIOP datagram, announced a size of0xD8000000and was rejected. GIOP 1.0 calls that bytebyte_order, a boolean; GIOP 1.1+ calls itflagswith the same bit at the same place.- The domain of a field depends on the version. Message type 7 (Fragment) does not exist in GIOP 1.0; reply status 4 and 5 (
LOCATION_FORWARD_PERM,NEEDS_ADDRESSING_MODE) and locate status 3..5 only exist in 1.2. Accepting them on an older header would produce a "valid" struct that contradicts itself, sovalidate_reply_status(value, minor_version)and friends take the version.
The body is CDR: a cursor, not indexes
The header is fixed; the body is CDR (Common Data Representation), CORBA's serialization. Its rule: every primitive is aligned on its natural size, counted from the start of the CDR stream. A ulong after a 2-byte short is preceded by 2 bytes of padding. Strings and sequence<octet> are length-prefixed. The layout of a Request also changed between GIOP 1.1 and 1.2 (service contexts moved from the front to after the operation name, object_key became a TargetAddress union, requesting_principal was removed, and the stub data became aligned on 8).
Indexing into the body with fixed offsets is therefore impossible. The module uses a small crate-internal cursor:
#![allow(unused)]
fn main() {
pub(super) struct Cursor<'a> {
    buf: &'a [u8],
    pos: usize,
    base: usize,          // 12 for a message body: alignment counts from the header
    little_endian: bool,
}

impl<'a> Cursor<'a> {
    fn align(&mut self, boundary: usize);          // CDR padding, bounded by the buffer
    fn align_body_1_2(&mut self);                  // Request/Reply 1.2 body aligned on 8
    fn read_u8(&mut self)  -> Result<u8, GiopParseError>;
    fn read_u16(&mut self) -> Result<u16, GiopParseError>;   // align(2) first
    fn read_u32(&mut self) -> Result<u32, GiopParseError>;   // align(4) first
    fn read_bytes(&mut self, len: usize) -> Result<&'a [u8], GiopParseError>;
    fn read_octet_sequence(&mut self) -> Result<&'a [u8], GiopParseError>;  // ulong len + bytes
    fn read_str(&mut self) -> Result<&'a str, GiopParseError>;              // + UTF-8, trailing NUL dropped
    fn rest(&self) -> &'a [u8];
}
}
Every read checks ensure_available first and returns UnexpectedEof otherwise: the cursor is the one place where bounds are enforced, and the parsers above it never index the buffer. It stays zero-copy: read_bytes, read_octet_sequence and read_str return slices of the original buffer, and rest() is how stub_data and body are obtained.
The second bug found on real frames lives here. The TargetAddress discriminant is a CDR short (2 bytes, followed by 2 bytes of padding before the next ulong), not an octet. Read as one byte, no real GIOP 1.2 Request decoded. The golden tests on corba.pcap lock these paddings in: without them, the operation name and service contexts of every real Request come out shifted.
The base field handles a subtlety: the alignment of a message body counts from the start of the message, header included (offset 0 is the magic), while an encapsulation — the opaque profile_data of an IOR profile — is its own CDR stream, starting at its own endianness byte. Cursor::encapsulation() restarts at base 0 and reads that byte.
A Request in GIOP 1.2 then reads as:
#![allow(unused)]
fn main() {
pub fn parse(body: &'a [u8], little_endian: bool) -> Result<Self, GiopParseError> {
    let mut cur = Cursor::new(body, little_endian);
    let request_id = cur.read_u32()?;
    let response_flags = cur.read_u8()?;
    let _reserved = cur.read_bytes(3)?;
    let target = parse_target_address(&mut cur)?;     // short discriminant + KeyAddr / ProfileAddr / ReferenceAddr
    let operation = cur.read_str()?;
    let service_contexts = parse_service_context_list(&mut cur)?;
    cur.align_body_1_2();                             // padding to 8, only if a body follows
    Ok(GiopRequest { request_id, response_flags, target, operation, service_contexts,
                     requesting_principal: None, stub_data: cur.rest() })
}
}
and the 1.0/1.1 layout is a separate function with the historical order, mapped onto the same struct (response_expected lands in response_flags, object_key becomes TargetAddress::KeyAddr).
Sender-controlled counters are bounded before allocation
A service context list and an IOR profile list are ulong count followed by count entries, and each entry is at least 8 bytes. A hostile count of 0xFFFFFFFF must not drive a Vec::with_capacity. The checks module bounds every counter against the bytes remaining before the loop:
#![allow(unused)]
fn main() {
pub fn validate_service_context_count(count: usize, remaining: usize) -> Result<(), GiopParseError> {
    if count > remaining / SERVICE_CONTEXT_MIN_LEN {
        return Err(GiopParseError::InvalidServiceContextCount { count, available: remaining });
    }
    Ok(())
}
}
Typed replies, degraded gracefully
A Reply carries a reply_status, and the meaning of its body depends on it. The decoder types that:
#![allow(unused)]
fn main() {
pub enum GiopReplyDetail<'a> {
    Results,                                              // NO_EXCEPTION: IDL-typed, opaque
    UserException { exception_id: &'a str, members: &'a [u8] },
    SystemException(GiopSystemException<'a>),             // repository id, minor code, completion status
    LocationForward(Ior<'a>),                             // the reference to retry against
    NeedsAddressingMode(u16),
    Undecoded,                                            // body unreadable, raw bytes kept in `body`
}
}
LocationForward is the interesting one for an analyst: the IOR says which host and port the client is being redirected to. Ior::iiop() returns the first readable IIOP profile — host, port, object key — decoded from its encapsulation:
#![allow(unused)]
fn main() {
if let GiopMessage::Reply(reply) = &packet.payload
    && let GiopReplyDetail::LocationForward(ior) = &reply.detail
    && let Some(iiop) = ior.iiop()
{
    println!("redirected to {}:{} ({})", iiop.host, iiop.port, ior.type_id);
}
}
Every level degrades on its own. An unreadable IIOP profile does not fail the IOR (iiop() returns None); an unreadable body does not fail the Reply (detail becomes Undecoded, the header and status are already reliable); an unreadable Request body does not fail the packet (payload becomes GiopMessage::Other). The reason is the pipeline: the blind probe calls GiopPacket::try_from on arbitrary TCP traffic, and the decode depth of the body must not change the classification, which only the header earns.
Stateless, on a protocol that ignores segment boundaries
GIOP messages routinely exceed the TCP MSS: an 8 KiB push Request on a 1460-byte segment is four segments. The parser is stateless — no TCP reassembly, no Fragment reassembly — so three behaviours were chosen deliberately:
- A message that overflows its segment is accepted and flagged, not rejected. The first segment carries the complete header and usually the complete Request header (request id, operation, object key), which is exactly what an analyst wants.
truncatedis set,wire_len()is bounded by the buffer, and the body is decoded on the bytes present. Before this choice, the first segment of every large message came outUnknownfrom the pipeline. - A segment may hold several messages. An ORB happily chains short messages (a LocateRequest and a Request) in one segment.
giop_messages(payload)iterates over them, stopping at the first byte that does not open a valid message or after a truncated one. - A message may start in the middle of a continuation segment. After a large message, the next one begins at offset 952 of a segment that does not start with the magic, and the stateless pipeline cannot label that segment. A caller that tracks flows and already knows the stream is GIOP can resynchronize with
find_giop_message(payload), which returns the offset of the first valid header (magic, version, type, reserved flag bits at zero), then read withgiop_messages. It is also how the GIOP message inside a MIOP multicast datagram is reached. It is not for classifying unknown traffic: four magic bytes in the middle of application data prove nothing.
Verified against tshark, message by message
The unit tests build synthetic bodies for the cases no ORB at hand emits (CancelRequest, OBJECT_FORWARD_PERM, ReferenceAddr...). Everything else is verified on real captures under pcaps_exemple/protocols/giop/, each with its provenance in SOURCE.md:
corba.pcapfrom the nDPI test corpus: GIOP 1.2 over TCP and over MIOP, both endiannesses, plus a ZIOP (compressed) message;- three captures attached to public Wireshark bug reports: LocateRequest/LocateReply, a fragmented 8 KiB Request whose Fragments start mid-segment, a GIOP 1.0
LOCATION_FORWARDwith an IIOP profile, aUSER_EXCEPTIONfrom CosNaming; - seven
lab_*.pcapproduced bytools/capture_giop.sh: a real omniORB 4.3.3 server and clients in a throwaway container, scripted to emit the same scenario in GIOP 1.0, 1.1 and 1.2, plus system exceptions, CloseConnection, MessageError and a client timeout. The recipe is replayable.
tests/giop_tshark_regression.rs replays every capture and compares each message, column by column, with an oracle produced by tools/giop_oracle.sh — tshark 4.6.6 with TCP reassembly disabled, i.e. the view of a stateless parser: type, version, flags, size, request id, reply and locate status, operation, exception id, IIOP host and port, object key and stub data lengths. The known divergences (tshark reports no request id on a 1.1 Fragment, and no operation on any Fragment) are named in tshark_only_columns, not hidden. A larger corpus (1 641 messages from other Wireshark issues), too big to redistribute, is replayed by an #[ignore] test.
The fuzz target parse_giop runs find_giop_message, then giop_messages, then dereferences every IOR it finds, asserting that no message ever covers more bytes than the buffer holds and that the iteration always progresses.
What is left out
- Stub data and user-exception members are IDL-typed: without the IDL they are opaque, and kept as raw slices.
- IIOP 1.1+ tagged components in a profile are not decoded.
- ZIOP (compressed GIOP) and MIOP framing are recognized as such but not decoded: the ZIOP body needs decompression, and MIOP is reached through
find_giop_message. - No reassembly, by design. Fragments are decoded individually (
GiopFragmentcarries the request id from 1.2 on); reassembling them belongs to a stateful layer above the parser.
Adding a new protocol
The crate is built so that adding a protocol is a mechanical job with the same shape every time. The reference document in the repository is METHODE_AJOUT_PROTOCOLE.md (in French); this chapter is its summary.
Mandatory principles
- The parser implements
TryFrom<&[u8]>, as a linear sequence: length pre-check, oneextract_*per constrained field in wire order, cross-field validations, then construction. The canonical model isntp.rs. - Zero-copy:
&'a [u8]for payloads and variable fields, scalars for fixed fields,from_be_bytesfor numbers. NoVec,String,to_vec()orclone()in a parsing struct. A&'a stronly when the protocol mandates UTF-8 and it was validated. - Any pre-allocation sized by a field of the packet goes through
bounded_capacity: a sender-controlled counter never drives aVec::with_capacityunbounded. - Errors in a dedicated file, with
thiserror, carrying the offending values. Never a bareString. - Checks in a separate file under
src/checks, not inline in the parser. - The main struct's rustdoc documents the wire format with a Mermaid
packet-betadiagram. - No
unwrap()in a parser. The CI runs clippy with-D warningsand theunwrap_used/expect_used/paniclints. - Golden tests use real frames from a capture under
pcaps_exemple/, with the pcap file and frame number cited in a comment. Synthetic bytes are for targeted unit tests (truncation, invalid value, limits) and are labelled as such.
Files to create
For an application protocol foo:
src/parse/application/protocols/foo.rs   the struct and its TryFrom
src/errors/application/foo.rs            enum FooError
src/checks/application/foo.rs            validate_* / extract_*
pcaps_exemple/protocols/foo/             a real capture + SOURCE.md
and one pub mod foo; in each layer's mod.rs.
1. The error type
#![allow(unused)]
fn main() {
use thiserror::Error;

#[derive(Debug, Error, PartialEq)]
#[non_exhaustive]
pub enum FooError {
    #[error("Packet too short: expected at least {expected} bytes, got {actual} bytes")]
    InvalidLength { expected: usize, actual: usize },
    #[error("Invalid Foo version: {0}")]
    InvalidVersion(u8),
    #[error("Invalid Foo message type: {0}")]
    InvalidMessageType(u8),
}
}
2. The checks
#![allow(unused)]
fn main() {
const FOO_MIN_LENGTH: usize = 8;

pub fn validate_foo_min_length(packet: &[u8]) -> Result<(), FooError> {
    if packet.len() < FOO_MIN_LENGTH {
        return Err(FooError::InvalidLength { expected: FOO_MIN_LENGTH, actual: packet.len() });
    }
    Ok(())
}

pub fn extract_foo_version(byte: u8) -> Result<u8, FooError> {
    let version = byte >> 4;
    if version != 1 {
        return Err(FooError::InvalidVersion(version));
    }
    Ok(version)
}
}
3. The parser
#![allow(unused)]
fn main() {
/// Foo Protocol Packet
///
/// ```mermaid
/// packet-beta
/// 0-3: "Version u4"
/// 4-7: "Flags u4"
/// 8-15: "Message Type u8"
/// 16-31: "Length u16"
/// 32-63: "Payload variable"
/// ```
#[derive(Debug, PartialEq)]
#[non_exhaustive]
pub struct FooPacket<'a> {
    pub version: u8,
    pub message_type: u8,
    pub length: u16,
    pub payload: &'a [u8],
}

impl<'a> TryFrom<&'a [u8]> for FooPacket<'a> {
    type Error = FooError;

    fn try_from(packet: &'a [u8]) -> Result<Self, Self::Error> {
        validate_foo_min_length(packet)?;

        let version = extract_foo_version(packet[0])?;
        let message_type = packet[1];
        let length = u16::from_be_bytes([packet[2], packet[3]]);
        validate_foo_announced_length(packet, length)?;

        Ok(FooPacket { version, message_type, length, payload: &packet[4..length as usize] })
    }
}
}
4. Plugging it into the dispatch table
Add a ProbeId::Foo and its run_probe arm in src/parse/dispatch.rs, then one line in RULES, choosing the route described in the application chapter:
- blind
rule("Foo", Guard::Tcp, ProbeId::Foo)only if a valid Foo payload cannot also be a valid payload of another detected protocol, or arbitrary text; - port-guarded
port_rule(..)otherwise, with a comment explaining why; - always with the transport guard the RFC imposes.
The position in the table matters: put the line where its priority belongs and say why in a comment. Then update the protocol lists of README.md and README-fr.md.
Do not add a variant to an exhaustive public enum in a minor version: that breaks users' match. The types the parser builds are #[non_exhaustive] so that new fields and variants stay additive.
5. Tests
Minimum for the unit tests: a valid packet, a too-short packet, an invalid version, an invalid announced length, an invalid type or flag.
Then, at PacketFlow level:
- at least one golden test on a real frame (Ethernet + IP + transport + Foo) checking that the label comes out;
- for a port-guarded protocol, the non-detection of the same bytes off the standard port;
- for a blind probe, a scan of the other protocols' corpus with a non-empty negative oracle, keyed by expected frame numbers so that a false positive and a false negative cannot cancel each other out;
- a structured valid seed in the relevant fuzz target: random bytes rarely get through Ethernet + IP + transport + Foo.
Extract a payload from a capture with:
tshark -r capture.pcap -Y "frame.number==5" -T fields -e tcp.payload
6. Checklist before commit
cargo fmt --all -- --check
cargo test --workspace --all-features
cargo clippy --workspace --all-targets --all-features -- -D warnings
cargo +nightly fuzz build
cargo audit
cargo deny check --hide-inclusion-graph
cargo semver-checks check-release   # public API vs the last published version